# ART Documentation # ART Docs import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; **ART** (Agent Reinforcement Trainer) is an open-source training framework for teaching agentic LLMs to improve **performance and reliability** through **experience**. ART provides a convenient wrapper around reinforcement learning techniques like **GRPO** (Group Relative Policy Optimization) to dramatically improve model performance while minimizing training costs. Our docs will guide you through the process of training your own agents to operate more **reliably and efficiently**.
## Why ART? - ART provides convenient wrappers for introducing RL training into **existing applications**. We abstract the training server into a modular service that your code doesn't need to interface with. - **Train from anywhere.** Run the ART client on your laptop and let the ART server kick off an ephemeral GPU-enabled environment, or run on a local GPU. - Integrations with hosted platforms like W&B, Langfuse, and OpenPipe provide flexible observability and **simplify debugging**. - ART is customizable with **intelligent defaults**. You can configure training parameters and inference engine configurations to meet specific needs, or take advantage of the defaults, which have been optimized for training efficiency and stability. - Direct integration with autoscaling GPUs through [W&B Training](https://docs.wandb.ai/guides/training/), making training and inference **faster** and **cheaper**. ## Installation ART agents can be trained from any client machine that runs python. To add to an existing project, run this command: ``` pip install openpipe-art ``` ## What is RL and when should I use it? RL (reinforcement learning) is a set of training techniques that allow AI models to learn from their own experience. Applying RL to an existing LLM can: - **Improve overall agent reliablity** - **Correct specific mistakes detected in QA or production** - **Build confidence in agent performance before deploying to users** Examples: - Train a deep research agent to search and parse information from a knowledge store. - Resolve annoying bugs in model behavior by adding new training examples. - Build a lightning fast voice agent that always follows its script. ## What do I need in order to use RL? Getting started may be simpler than you expect. ### Things you DO need: ### Things you DON'T need: ## How to start using ART? The ART client can be installed into projects designed to run on any machine that runs python. ART server can be run on any machine with a GPU, including your local laptop or within any cloud environment equipped with GPUs. To train an agent for free, try training a model to play 2048 on a free GPU in Google Colab. Or install ART into your existing project to start improving your agent's performance! # Quick Start import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; In this Quick Start tutorial, we'll be training Qwen3 14B Instruct to play [2048](https://play2048.co/), a simple game that requires forward planning and basic math skills. Reading time: 15 min Training time: 2 hours Total cost: Free! ## Step 1: Provision W&B API key [ART](https://github.com/OpenPipe/art) is an open source library and works across infra and observability providers. To keep things simple in this tutorial, we'll exclusively use Weights & Biases services, which means we'll only need to provision one API key. We'll use these services: * **W&B Training** - autoscale GPUs for inference and training * **W&B Models** - record metrics like reward * **W&B Weave** - record your model's traces as it generates completions * **W&B Artifacts** - store and manage your model's checkpoints Weights & Biases currently provides a small free tier for all the services we'll use during this quickstart, so you shouldn't need to add a credit card to get started. - [Weights & Biases](https://wandb.ai/home) Once you have your Weights & Biases API key, open the [notebook](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/2048/2048.ipynb) in Google Colab and set it in the **Environment Variables** cell. Then continue on to the next step. ## Step 2: Run the notebook At the top of the [notebook](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/2048/2048.ipynb) you should see a small **Run all** button. Press it to begin training your model. ## Step 3: Track metrics While your run progresses, observe its traces and metrics in your [W&B workspace](https://wandb.ai/home). You should start seeing some progress in the first 20-30 steps. For a guide to the metrics ART logs automatically and how to add your own, see [Tracking Metrics](/features/tracking-metrics). If you have questions along the way, please ask in the [Discord](https://discord.gg/zbBHRUpwf4). Happy training! # Installation + Setup import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; ### Installing ART The ART client can be installed into projects designed to run on any machine that runs python. ```bash pip install openpipe-art ``` ### Running the server locally The ART server can be run locally on any machine with a GPU. To install the backend dependencies required for training and inference, you can install the `backend` extra: ```bash pip install --extra-index-url https://download.pytorch.org/whl/cu128 \ "openpipe-art[backend]" ``` ```python from art import TrainableModel, gather_trajectory_groups from art.local.backend import LocalBackend backend = LocalBackend() model = TrainableModel( name="agent-001", project="my-agentic-task", base_model="OpenPipe/Qwen3-14B-Instruct", ) await model.register(backend) ... the rest of your code ... ``` CUDA 13 hosts use `openpipe-art[backend-cu130]` and the PyTorch `cu130` index. ### Running Megatron On a supported CUDA 12 trainer image, one install command provides ART's controller, Monarch runtime, and the locked Megatron runtime contract: ```bash pip install --extra-index-url https://download.pytorch.org/whl/cu128 \ "openpipe-art[megatron]" ``` CUDA 13 hosts use `openpipe-art[megatron-cu130]` with `https://download.pytorch.org/whl/cu130`. Megatron currently requires Python 3.12. The first trainer launch materializes the exact trainer environment in a content-addressed node-local cache. No ART checkout or `setup.sh` invocation is required. The image remains responsible for the NVIDIA driver and CUDA toolkit. For cross-host training it must also provide the NCCL network transport, MOFED/RDMA devices, and the kernel capabilities described in the multi-node deployment guide. ART validates these before allocating the model. Tinker users install `openpipe-art[tinker]`; serverless users need only `openpipe-art`. These profiles do not install Megatron or vLLM dependencies. ### Using a managed autoscaling backend Instead of managing the GPUs and training processes yourself, you can optionally send inference and training requests to the W&B Training cluster, which autoscales to match your job's demand. To do so, install `openpipe-art` without any extras and use `ServerlessBackend`: ```bash pip install openpipe-art ``` ```python from art import TrainableModel, gather_trajectory_groups from art.serverless.backend import ServerlessBackend backend = ServerlessBackend() model = TrainableModel( name="agent-001", project="my-agentic-task", base_model="OpenPipe/Qwen3-14B-Instruct", ) await model.register(backend) ... the rest of your code ... ``` To learn more about the ART client and server, see the docs below.
The client is responsible for interfacing between your code and the ART backend.
The backend is responsible for generating tokens and training your models.
# Multi-node deployment ART's distributed runtime consumes a Monarch host mesh. SkyPilot can provision that mesh, but it is a deployment tool rather than an ART dependency. The ART process does not launch another SkyPilot cluster from inside its allocation. ## Controller program The bootstrap accepts a source script or import path to a top-level async function. A script reference such as `train.py:main` adds the script's directory to every ART-owned worker's Python path, so source synchronized by SkyPilot does not need to be packaged first. SkyPilot runs the bootstrap on every node, but only rank 0 imports the module and invokes the controller. `examples/multinode/program.py` is a complete CPU-runnable Yes/No/Maybe smoke: ```python import asyncio import os import socket import art from art.distributed import ( ArtLaunchContext, ArtRuntime, InstalledAsyncCallable, compile_topology, ) REWARDS = {"yes": 0.5, "no": 0.75, "maybe": 1.0} async def rollout( _model: art.TrainableModel, answer: str, _config: None ) -> art.Trajectory: messages: art.MessagesAndChoices = [ {"role": "user", "content": f"Respond with {answer}."}, {"role": "assistant", "content": answer}, ] return art.Trajectory( messages_and_choices=messages, reward=REWARDS[answer], metadata={ "answer": answer, "hostname": socket.gethostname(), "process_id": os.getpid(), }, ) async def main(launch: ArtLaunchContext) -> None: host_count = launch.host_count runtime = await ArtRuntime.start( launch.host_mesh, compile_topology( cluster=launch.homogeneous_cluster( cpu_slots=1, startup_timeout_s=90, rpc_timeout_s=30, ) ), ) try: workers = tuple(range(host_count)) executor = runtime.rollout_executor( InstalledAsyncCallable.from_callable(rollout), target_workers=host_count, ) executor.set_workers(workers) model = art.TrainableModel( name="multinode-smoke", project="art", base_model="not-loaded", run_name="multinode-smoke", ) trajectories = [] for answer in REWARDS: trajectories.extend( await asyncio.gather( *( executor.run(worker, rollout, model, answer, None) for worker in workers ) ) ) answers = [ str(trajectory.metadata["answer"]) for trajectory in trajectories ] expected = [answer for answer in REWARDS for _ in workers] placements = { (trajectory.metadata["hostname"], trajectory.metadata["process_id"]) for trajectory in trajectories } if answers != expected or len(placements) != host_count: raise RuntimeError( f"distributed rollout mismatch: {answers=}, {placements=}" ) print(f"ART_MULTINODE_SMOKE_PASS hosts={host_count} answers={answers}") finally: await runtime.close() ``` The controller receives an `ArtLaunchContext` once, while the top-level `rollout` runs in one process on each host. The context owns the attached host mesh and builds a homogeneous typed cluster without exposing provider environment variables. Both functions must be installed or synchronized at the same import paths on every node; ART sends verified import references and never ships opaque closures. The dummy `TrainableModel` is serialized for the rollout contract but never loaded, so this validates the package, host admission, process placement, public trajectory types, and cleanup without a GPU or inference server. The distributed service APIs are opt-in. Existing single-node programs continue to construct and use `LocalBackend` exactly as before: ```python from art.local import LocalBackend backend = LocalBackend() ``` ## SkyPilot Start with `examples/multinode/skypilot.yaml`. It is an intentionally CPU-only two-node smoke that runs all three bounded rollouts on each host without reserving training GPUs or provisioning the managed vLLM runtime. For source-based GPU training, replace its resources and setup with the desired topology and run the CUDA-detecting cluster setup: ```yaml resources: accelerators: H200:8 setup: | set -euo pipefail INSTALL_MULTINODE=true bash scripts/setup.sh run: | set -euo pipefail export NCCL_NET=IB exec .venv/bin/art-monarch skypilot \ --program train.py:main ``` `set -euo pipefail` is required because SkyPilot runs multiline setup under Bash without enabling fail-fast behavior. For source development, `scripts/setup.sh` selects the CUDA-matched root and private trainer locks and builds HybridEP. It does not install system packages. The image or cluster bootstrap must provide the NVIDIA driver and toolkit, native build tools, NCCL network transport, MOFED/RDMA devices, and the required kernel modules. The CPU example only syncs the root `distributed` extra. Setup is cluster provisioning, not service startup. `art-monarch`, trainer actors, and managed vLLM processes never invoke these shell scripts. Source checkouts launch the already-built `vllm_runtime/.venv`; release wheels may materialize their bundled, locked vLLM environment into a content-addressed cache on first use. Any GPU workload spanning hosts must set one explicit NCCL network contract in its `ClusterSpec`, for example `nccl_transport=NcclTransportSpec(net_name="IB")`, and set `NCCL_NET` to that exact registered name on every node. `IB` covers built-in InfiniBand/RoCE; external network plugins use their registered NCCL name. Before model allocation, ART runs a small collective in both the trainer and managed-vLLM environments and requires each rank to report that exact selected module. It never retries with Socket. Deployment qualification remains responsible for all-GPU bandwidth, GPU Direct RDMA, HCA, and GID validation. Cross-host HybridEP uses `NixlTransportSpec()`. If `metadata_store` is omitted, the controller starts a checksum-pinned etcd process, publishes its routable endpoint, health-checks it from every host, and owns its cleanup. An explicitly managed endpoint remains supported. If `ART_VLLM_RUNTIME_BIN` is set, it must point directly to a standard `.venv/bin/art-vllm-runtime-server` executable. ART derives the matching Python, runtime root, environment, and working directory from that path so the preflight cannot certify a different runtime. Arbitrary command wrappers fail closed. For a published release wheel, install the profile matching the host CUDA toolkit. For CUDA 12: ```yaml setup: | set -euo pipefail uv venv --python 3.12 --seed .venv .venv/bin/pip install \ --extra-index-url https://download.pytorch.org/whl/cu128 \ "openpipe-art[megatron]==VERSION" ``` For CUDA 13, use `openpipe-art[megatron-cu130]==VERSION` and the PyTorch `cu130` index. These commands install ART, Monarch, and the CUDA-specific NIXL wheel. The example uses the supported image's `uv` installation to provision Python 3.12. The first trainer launch materializes the pinned Megatron environment, builds source-only CUDA components such as CUDA 12 Apex and ART's HybridEP when needed, and reuses the immutable result on later launches. NIXL and its UCX GDA plugin come from the official relocatable wheel; ART bundles only the matching pinned headers needed to build HybridEP. Release wheels use content-addressed managed Megatron and vLLM runtime bundles. Only wheels built with `scripts/build_package.py` contain those bundles. The install profile provides `uv`; first use needs package-index access unless the node-local cache was prewarmed. `examples/multinode/skypilot_training.yaml` runs a real two-host DP2 SFT step from the published wheel. It synchronizes only the user program, not an ART checkout. Point `ART_SHARED_ROOT` at an existing path mounted on every host, then launch: ```fish sky launch -c art-multinode-training \ --env ART_SHARED_ROOT=/mnt/shared/art-multinode-release \ examples/multinode/skypilot_training.yaml ``` Launch it from the project root: ```fish sky launch -c art-multinode examples/multinode/skypilot.yaml ``` One task rank runs on each allocated node. Every rank owns one Monarch worker subprocess; rank 0 also attaches the host mesh and runs the controller program. Rank-0 program completion or failure closes the lifecycle sockets and releases the peer task ranks. No manual SSH or per-node command is required. Each task invocation owns fresh worker loops and terminates them after the host mesh shuts down. A later `sky exec` starts new loops; ART does not reattach a second controller to completed workers. Ctrl-C disconnects SkyPilot log streaming; it does not stop the remote job. Check the queue and cancel explicitly when needed: ```fish sky queue art-multinode sky cancel art-multinode JOB_ID ``` Only after the previous job is terminal, reuse an existing cluster without rerunning setup: ```fish sky exec art-multinode examples/multinode/skypilot.yaml ``` `sky exec` synchronizes the workdir before scheduling, so running it while the previous job is live can change files under that job. Use `sky launch` instead when setup, mounts, the image, SkyPilot config, a wheel, `pyproject.toml`, or a lockfile changed. Setting `num_nodes: 1` uses the same controller on one node. For a local process that explicitly wants the same Monarch service APIs, ART can own one loopback worker directly: ```fish .venv/bin/art-monarch local \ --program examples/multinode/program.py:main \ --port 0 \ --startup-timeout 90 ``` Port `0` selects a fresh loopback port. `ArtRuntime.start_local(...)` is the equivalent library API. It accepts the same one-host compiled topology used by multi-node code and owns the worker for the runtime lifetime. SkyPilot provides `SKYPILOT_NODE_RANK`, `SKYPILOT_NODE_IPS`, and `SKYPILOT_NUM_NODES`; ART validates and translates them internally. Port `22222` is the Monarch worker port and `22223` is its job-lifecycle port. Pass `--port N` to reserve `N` and `N + 1` instead. These ports must be reachable between allocated nodes but must not be publicly exposed: ART's Monarch runtime uses unauthenticated `trust_all_connections` transport. ## Existing SSH hosts For preallocated machines, start and own all workers from one controller command: ```fish .venv/bin/art-monarch ssh \ --host gpu-a=10.0.0.10 \ --host gpu-b=10.0.0.11 \ --python /shared/project/.venv/bin/python \ --program /shared/project/train.py:main ``` Each value is `SSH_TARGET=WORKER_HOST`. Omit `=WORKER_HOST` when the SSH target is also the private address to which Monarch should bind. The controller must have both passwordless SSH access to every `SSH_TARGET` and a direct trusted private or VPN route to every `WORKER_HOST:N`. SSH options such as `ProxyJump` or `--ssh-arg=-F` affect only launch and stop commands; they do not tunnel Monarch traffic. SSH mode uses only worker port `N`, not SkyPilot's lifecycle port `N + 1`. The selected Python executable and source script must exist at the same paths on every host. ART uses non-interactive SSH, verifies that each launch-specific worker PID owns its listener, and monitors each foreground SSH process for the controller lifetime. A pre-existing listener is a hard error rather than a worker to reattach. SIGTERM and SIGHUP trigger bounded remote cleanup before the controller exits. The lower-level `worker` and `controller` subcommands remain available for schedulers or process supervisors that own worker lifecycle themselves. Those supervisors must replace worker loops before a subsequent controller attach. # ART Notebooks import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify";
| Agent Task | Notebook | Description | Performance | | ------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------ | --------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | **ART•E [Serverless]** | [🏋️ Train agent](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/art-e.ipynb) | Qwen3 14B learns to search emails using RULER | | | **2048 [Serverless]** | [🏋️ Train agent](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/2048/2048.ipynb) | Qwen3 14B learns to play 2048 | | | **ART•E LangGraph** | [🏋️ Train agent](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/langgraph/art-e-langgraph.ipynb) | Qwen2.5 7B learns to search emails using LangGraph | [Link coming soon] | | **MCP•RL** | [🏋️ Train agent](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/mcp-rl/mcp-rl.ipynb) | Qwen2.5 3B masters the NWS MCP server | [Link coming soon] | | **Temporal Clue** | [🏋️ Train agent](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/temporal_clue/temporal-clue.ipynb) | Qwen2.5 7B learns to solve Temporal Clue | [Link coming soon] | | **Tic Tac Toe** | [🏋️ Train agent](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/tic_tac_toe/tic-tac-toe.ipynb) | Qwen2.5 3B learns to play Tic Tac Toe | | | **Codenames** | [🏋️ Train agent](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/codenames/Codenames_RL.ipynb) | Qwen2.5 3B learns to play Codenames | | | **AutoRL [RULER]** | [🏋️ Train agent](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/auto_rl.ipynb) | Train Qwen2.5 7B to master any task | [Link coming soon] |
# Frequently Asked Questions import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; ART (Agent Reinforcement Trainer) is a reinforcement learning framework that allows for easy training of LLM-based agents using GRPO (as well as PPO and other techniques in the future). It's focused on best-in-class training efficiency ergonomic agentic multi-turn support. By allowing an LLM to make multiple attempts at accomplishing a task and scoring each rollout’s performance, we shift the model's weights to make it more likely to perform the way it did in its best runs and to avoid its least effective behavior. Yes. If you have a standard Hugging Face–style LoRA adapter directory (e.g., produced by Unsloth/PEFT), pass the adapter folder path as the `base_model` when creating your `TrainableModel`. ```python import art model = art.TrainableModel( name="agent-001", project="my-agentic-task", base_model="/path/to/my_sft_lora_adapter", # HF-style adapter dir ) ``` ART will load the adapter as the initial checkpoint and proceed with RL updates from there. This flow chart shows a highly simplified flow of how ART optimizes your agent. Your code is responsible for actually running the agent in the environment it will operate in, as well as scoring the trajectory (deciding whether the agent did a good job or not). ART is then able to take those trajectories and scores and use them to iteratively train your agent and improve performance. ![](/images/faq/art-loop.webp) Over the course of many training steps, the model learns what strategies help it succeed at its task, and which strategies are unhelpful. Through this process, small models like Llama 3.1 8B and and Qwen 3 8B can learn to outperform much larger and more expensive models like o3 and sonnet-4. Aberrations in model performance identified during QA or in production can be instantly fixed by adding a similar training example to the training set. The resulting model is small, fast, and best-in-class at its task. It can be run on any cloud, including locally within a VPC. By separating the ART backend into a separate service, we've been able to keep the ART frontend extremely narrow and clean. This makes it much easier to embed it into existing production applications, while allowing the heavy backend to be run on separate, powerful machines with appropriate GPU resources. We've included an open-source ART backend and over time we expect more providers to implement hosted ART backends as well, giving users choice and convenience in where their models are trained. Note however that the initial release assumes that the frontend and backend are running on the same machine with a GPU available. To get good results with ART, we recommend first ensuring your task meets the following requirements: - Open source models can complete the task at least 30% of the time already. If you try to use ART on a task that is too far out of distribution, it likely won't be able to teach your model efficiently. - You can easily verify whether a task was completed successfully. ART, like all reinforcement-learning approaches, works by training a model to maximize a reward. To use it successfully, you need to be able to define some kind of quantifiable reward for the model to optimize against. Rewards can be objective ("does this output match the golden data from my training set") or subjective ("does this output satisfy my LLM-as-judge") but must be consistent and quantifiable. - Your agent can be run many times without affecting the real world. ART currently builds on GRPO, an RL algorithm that involves running many agents in parallel and then using the difference in the rewards they achieve as a stable training signal. This means that you need to be able to run the model many times in the same scenario as part of training, which isn't a good fit for agents that make changes in the external world. We are committed to maintaining ART as a full-featured open source project. We will also deploy an optional hosted ART backend for users who don't want to manage GPU infrastructure on their own. RL can often be more expensive than other training methods like SFT for a given dataset size. In our experiments, training runs often cost between $15 and $200 in GPU time. We are actively working on improving efficiency and welcome contributions in this area; there is still a lot of low-hanging fruit to pick here. This is theoretically possible, and an area that we're interested in exploring! However, there are practical challenges that make this a bit of a longer-term project. For now, we recommend training a reward model on your production feedback, and then using ART to optimize your model or agent against that reward model. We designed the ART architecture to make training agents trivial. But under the hood we are using GRPO, which is a general purpose RL technique and the same one used to train R1, the frontier open-source reasoning model. ART is very effective at optimizing any LLM task for which you can define a quantifiable reward signal. # ART Training Loop import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; ART's functionality is divided into a [**client**](/fundamentals/art-client) and a [**backend**](/fundamentals/art-backend). The OpenAI-compatible client is responsible for interfacing between ART and your codebase. Using the client, you can pass messages and get completions from your LLM as it improves. The backend runs independently on any machine with a GPU. It abstracts away the complexity of the inference and training portions of the RL loop while allowing for some custom configuration. An outline of the training loop is shown below: 1. **Inference** 1. Your code uses the ART client to perform an agentic workflow (usually executing several rollouts in parallel to gather data faster). 2. Completion requests are routed to the ART backend, which runs the model's latest LoRA in vLLM. 3. As the agent executes, each `system`, `user`, and `assistant` message is stored in a Trajectory. 4. After your rollouts finish, your code assigns a `reward` to each Trajectory, with higher rewards indicating better performance than low ones. 2. **Training** 1. When all rollouts have finished, Trajectories are grouped and sent to the backend. Inference is blocked while training executes. 2. The backend trains your model using GRPO, initializing from the latest checkpoint (or an empty LoRA on the first iteration). 3. The backend saves the newly trained LoRA to a local directory and loads it into vLLM. 4. Inference is unblocked and the loop resumes at step 1. This training loop runs until a specified number of inference and training iterations have completed. This describes the default shared-resource loop. `PipelineTrainer` can also run with `LocalBackend` in dedicated mode, where training and inference stay on separate GPUs and the latest served step advances only after vLLM reloads the new LoRA. Training and inference use both the ART **client** and **backend**. Learn more by following the links below!
The client is responsible for interfacing between your code and the ART backend.
The backend is responsible for generating tokens and training your models.
# ART Client import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; One of ART's primary goals is to minimize the amount of setup necessary to begin benefitting from RL within an existing codebase. The ART client is a lightweight object that allows you to run inference and train models against either local or remote backends. That means that you can run your agent anywhere, including on a laptop without a powerful GPU, and still get all the performance benefits of training and generating tokens on a H100. Pretty cool! If you're curious about how ART allows you to run training and inference either remotely or locally depending on your development machine, check out the backend docs below. Otherwise, let's dive deeper into the client! Run training and inference on autoscaling GPUs. Run training and inference on your local machine. ## Initializing the client The client that you'll use to generate tokens and train your model is initialized through the `art.TrainableModel` class. ```python import art model = art.TrainableModel( # the name of your model as it will appear in W&B # and other observability platforms name="agent-001", # keep your project name constant between all the models you train # for a given task to consistently group metrics project="my-agentic-task", # the model that you want to train from base_model="OpenPipe/Qwen3-14B-Instruct", ) ``` Once you've initialized your [backend](/fundamentals/art-backend), you can register it with your model. This sets up all the wiring to run inference and training. ```python # managed training backend = ServerlessBackend() # local training backend = LocalBackend() await model.register(backend) ``` ### Initializing from an existing SFT LoRA If you've already fine-tuned a model with SFT using a LoRA adapter (e.g., Unsloth/PEFT) and have a standard Hugging Face–style adapter directory, you can start RL training from those weights by passing the adapter directory path as `base_model` when creating your `TrainableModel`. Why this? - Warm-start from task-aligned weights to reduce steps/GPU cost. - Stabilize early training, especially for small models (1B–8B) that may get near-zero rewards at RL start. ```python import art model = art.TrainableModel( name="agent-001", project="my-agentic-task", # Point to the local SFT LoRA adapter directory # (e.g., contains adapter_config.json and adapter_model.bin/safetensors) base_model="/path/to/my_sft_lora_adapter", ) ``` ART will load the adapter as the initial checkpoint and proceed with RL updates from there. You're now ready to start training your agent. ## Running inference Your model will generate inference tokens by making requests to a vLLM server running on whichever backend you previously registered. To route inference requests to this backend, follow the code sample below. ```python openai_client = model.openai_client() messages: art.Messages = [ { "role": "system", "content": "...", }, { "role": "user", "content": "..." } ] chat_completion = await openai_client.chat.completions.create( messages=messages, model=model.get_inference_name(), max_tokens=100, timeout=100, tools=[...] ) print(chat_completion.choices[0].message.tool_calls) ``` As your model learns to become more capable at the task, its weights will update and each new LoRA instance will be automatically loaded onto the vLLM server running on your backend. The registration and inference process shown above will ensure that your inference requests are always routed to the latest version of the model, saving you a lot of complexity! ## Training the model Before training your model, you need to provide a few scenarios that your agent should learn from. While completing these scenarios, its weights will update to avoid past mistakes and reproduce successes. It's best to provide at least 10 scenarios that adequately represent the real scenarios your agent will handle after it's deployed. ```python class Scenario: # add whatever fields differ from one real-world scenario to another field_1: str field_2: float scenarios = [ Scenario( field_1: "hello", field_2: 0 ), Scenario( field_1: "world!", field_2: 1 ) ] ``` Define a rollout function that runs the agent through an individual scenario. ```python # define a rollout function that puts the model through its paces for a given scenario async def rollout(model: art.Model, scenario: Scenario) -> art.Trajectory: openai_client = model.openai_client() trajectory = art.Trajectory( messages_and_choices=[{ "role": "system", "content": "..." }, { "role": "user", "content": "... }] ) # generate a completion using the client chat_completion = await openai_client.chat.completions.create( messages=trajectory.messages(), model=model.get_inference_name() ) choice = chat_completion.choices[0] trajectory.messages_and_choices.append(choice) # determine how well the agent did during this particular run agent_performance_score: float = ... trajectory.reward = agent_performance_score return trajectory ``` Now that your training scenarios and rollout function are declared, training the model is straightforward. The following code trains the model for **50** steps, allowing the agent **8** attempts at each training scenario during each step. Since a reward is assigned to each Trajectory that the rollout function returns, the agent will learn to produce completions that are more similar to those that resulted in high rewards in the past, and will shy away from behavior that resulted in low rewards. ```python async def train(): # train for 50 steps for _ in range(await model.get_step(), 50): # Trajectories produced using the same training scenario are automatically grouped train_groups = await art.gather_trajectory_groups( ( art.TrajectoryGroup(rollout(model, scenario) for _ in range(8)) for scenario in scenarios ), pbar_desc="gather", ) print("num train groups:", len(train_groups)) # num train groups: 2 print("length of each train group:", len(train_groups[0])) # length of each train group: 8 # send the grouped trajectories to the backend and wait until training finishes result = await backend.train(model, train_groups, learning_rate=1e-5) await model.log(train_groups, metrics=result.metrics, step=result.step, split="train") # once backend.train finishes for the current step # the backend updates the LoRA weights for inference and # the training loop continues until 50 steps have completed ``` To see the ART client and backend working together in action, check out our Summarizer tutorial or one of the notebooks! If you have questions on how to integrate the ART client into your own codebase, please ask in the [Discord](https://discord.com/channels/1359674493949448375/1359674622965973185)!
Teach a summarizer agent to outperform Sonnet 4.
Put the ART client and server in action in one of our notebooks!
# ART Backend import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; ART divides the logic for training an agent into two distinct abstractions. The [client](/fundamentals/art-client) is responsible for interfacing with the environment in which the agent runs and for sending inference and training requests to the backend. The **backend** is responsible for generating tokens at inference time, updating the agent's weights based on past performance, and managing GPU memory as it switches from inference to training mode. This separation of concerns simplifies the process of teaching an agent to improve its performance using RL. While the backend's training and inference settings are highly configurable, they're also set up to use **intelligent defaults** that save beginners time while getting started. However, there are a few important considerations to take before running your first training job.
## Managed or local training ART provides two backend classes: * `ServerlessBackend` - train remotely on autoscaling GPUs * `LocalBackend` - run your agent and training code on the same machine If your agent is already set up on a machine equipped with an advanced GPU and you want to run training on the same machine, use `LocalBackend`. If your agent is running on a machine without an advanced GPU (this includes most personal computers and production servers), use `ServerlessBackend` instead. `ServerlessBackend` optimizes speed and cost by autoscaling across managed clusters. ### ServerlessBackend Setting up `ServerlessBackend` requires a W&B API key. Once you have one, you can provide it to `ServerlessBackend` either as an environment variable or initialization argument. ```python from art.serverless.backend import ServerlessBackend backend = ServerlessBackend( api_key="my-api-key", # or set WANDB_API_KEY in the environment ) ``` As your training job progresses, `ServerlessBackend` automatically saves your LoRA checkpoints as W&B Artifacts and deploys them for production inference on W&B Inference. ### LocalBackend The `LocalBackend` class runs a vLLM server and either an Unsloth or torchtune instance on whatever machine your agent itself is executing. This is a good fit if you're already running your agent on a machine with a GPU. To declare a `LocalBackend` instance, follow the code sample below: ```python from art.local import LocalBackend backend = LocalBackend( # set to True if you want your backend to shut down automatically # when your client process ends in_process: False, # local path where the backend will store trajectory logs and model weights path: './.art', ) ``` If you're using `PipelineTrainer`, `LocalBackend` is currently supported only in dedicated mode, where training and inference run on separate GPUs. ```python from art import TrainableModel from art.dev import InternalModelConfig from art.local import LocalBackend backend = LocalBackend(path="./.art") model = TrainableModel( name="pipeline-localbackend", project="my-project", base_model="Qwen/Qwen3-0.6B", _internal_config=InternalModelConfig( trainer_gpu_ids=[0], inference_gpu_ids=[1], ), ) ``` Shared `LocalBackend` still pauses inference during training, so ART rejects that configuration for `PipelineTrainer`. In dedicated mode, a new checkpoint becomes the default inference target only after its LoRA has been reloaded into vLLM. That checkpoint publication flow is backend-specific, so `save_checkpoint` does not have identical semantics across every ART backend. Requests that are already in flight keep using the adapter they started with; the reload only affects subsequent routing to the latest served step. ## Using a backend Once initialized, a backend can be used in the same way regardless of whether it runs locally or remotely. ```python BACKEND_TYPE = "serverless" if BACKEND_TYPE == "serverless": from art.serverless.backend import ServerlessBackend backend = await ServerlessBackend() else: from art.local import LocalBackend backend = LocalBackend() model = art.TrainableModel(...) await model.register(backend) # ...training code... ``` To see `LocalBackend` and `ServerlessBackend` in action, try the examples below.
Use ServerlessBackend to train an agent to play 2048.
Use LocalBackend to train a SOTA summarizing agent.
# RULER import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; # 📏RULER: Relative Universal LLM-Elicited Rewards RULER (Relative Universal LLM-Elicited Rewards) is a general-purpose reward function that uses an LLM-as-judge to rank multiple agent trajectories. It requires no labeled data, expert feedback, or hand-crafted reward functions, yet reliably improves agent performance. RULER Performance Results ## Key Benefits - **No labeled data required**: RULER works by comparing trajectories against each other - **General-purpose**: Can be applied to a wide variety of RL tasks without modification - **Fast development**: Can reduce implementation time by 2-3x compared to hand-crafted rewards - **Strong performance**: Often matches or exceeds hand-crafted reward functions ## How RULER Works RULER leverages two key insights: 1. **Relative scoring is easier than absolute scoring**: It's easier for an LLM to rank several solutions relative to each other than to score them in isolation 2. **GRPO only needs relative scores**: Since GRPO normalizes scores within each group, only the relative rankings matter, not absolute values The process: 1. Generate N trajectories for a given scenario 2. Pass all N trajectories to RULER 3. RULER deduplicates common prefixes (e.g., identical system messages) 4. An LLM judge scores each trajectory from 0 to 1 based on goal achievement 5. These scores are used directly as rewards in GRPO training ## Basic Usage ```python import art from art.rewards import ruler_score_group # Create a TrajectoryGroup from your trajectories group = art.TrajectoryGroup([...]) # List of art.Trajectory objects # Use RULER to score them judged_group = await ruler_score_group( group, "openai/o3", debug=True # Shows the judge's reasoning ) # Access the scores if judged_group: # Check if judging succeeded for traj in judged_group.trajectories: print(f"Reward: {traj.reward}") print(f"RULER explanation: {traj.logs[-1]}") ``` ## Complete Example: Joke Generation Here's a toy example showing how RULER ranks different quality trajectories: ```python import asyncio import art from art.rewards import ruler_score_group from openai.types.chat.chat_completion import Choice from openai.types.chat import ChatCompletionMessage async def main(): # Initial messages shared by all trajectories initial_messages = [ {"role": "system", "content": "You are a comedy writer. Generate funny jokes based on the given topic."}, {"role": "user", "content": "Tell me a funny joke about computers"} ] # Create three trajectories with different quality responses good_trajectory = art.Trajectory( messages_and_choices=[ *initial_messages, Choice(finish_reason="stop", index=0, message=ChatCompletionMessage( role="assistant", content="Why don't computers ever get invited to parties?\n\nBecause they always crash! 🥁\n\nBut seriously, have you tried turning them off and on again?" )) ], reward=0.0 ) mediocre_trajectory = art.Trajectory( messages_and_choices=[ *initial_messages, Choice(finish_reason="stop", index=0, message=ChatCompletionMessage( role="assistant", content="What do you call a computer that doesn't work?\n\nBroken." )) ], reward=0.0 ) off_topic_trajectory = art.Trajectory( messages_and_choices=[ *initial_messages, Choice(finish_reason="stop", index=0, message=ChatCompletionMessage( role="assistant", content="I don't really know jokes about computers, but here's a fact: The sky is blue because of Rayleigh scattering." )) ], reward=0.0 ) # Create a TrajectoryGroup and use RULER to score group = art.TrajectoryGroup([good_trajectory, mediocre_trajectory, off_topic_trajectory]) judged_group = await ruler_score_group(group, "openai/o3", debug=True) # Display rankings if judged_group: sorted_trajectories = sorted(judged_group.trajectories, key=lambda t: t.reward, reverse=True) for rank, traj in enumerate(sorted_trajectories, 1): messages = traj.messages() print(f"Rank {rank}: Score {traj.reward:.3f}") print(f" Response: {messages[-1]['content'][:50]}...") asyncio.run(main()) ``` ### Example Output ``` [RULER] Pretty-printed LLM choice JSON: { 'scores': [ { 'trajectory_id': '1', 'explanation': 'This joke cleverly connects computer crashes with social situations, making it relatable and humorous. It also includes a common tech support line for added humor.', 'score': 0.9 }, { 'trajectory_id': '2', 'explanation': "While this joke is straightforward and a pun, it's quite simple and lacks depth. Still, it stays relevant to the computer theme.", 'score': 0.5 }, { 'trajectory_id': '3', 'explanation': 'This trajectory fails to deliver a joke about computers, instead providing an unrelated fact, resulting in a very low score.', 'score': 0.1 } ] } Rank 1: Score 0.900 Response: Why don't computers ever get invited to parties?... Rank 2: Score 0.500 Response: What do you call a computer that doesn't work?... Rank 3: Score 0.100 Response: I don't really know jokes about computers, but h... ``` ## Customization ### Judge Model You can use any LLM supported by LiteLLM as the judge: ```python # Using o4-mini await ruler_score_group(group, "openai/o4-mini") # Using Claude await ruler_score_group(group, "anthropic/claude-sonnet-4-20250514") # Using local models await ruler_score_group(group, "ollama/qwen3:32b") ``` ### Extra LiteLLM Parameters You can pass additional parameters to LiteLLM for fine-tuning the judge behavior: ```python # Adjust temperature and max tokens await ruler_score_group( group, "openai/o3", extra_litellm_params={"temperature": 0.7, "max_tokens": 1000} ) # Use custom API base for local models await ruler_score_group( group, "openai/gpt-4", extra_litellm_params={"api_base": "http://localhost:8000"} ) ``` ### Custom Rubric While the default rubric works well for most tasks, you can provide a custom one: ```python custom_rubric = """ - Prioritize responses that are concise and clear - Penalize responses that include emojis or informal language - Reward responses that cite sources """ await ruler_score_group( group, "openai/o3", rubric=custom_rubric ) ``` ### Using Raw Message Lists If you're not using `art.Trajectory` objects, you can use the lower-level `ruler` function: ```python from art.rewards import ruler # Each message list is a list of ChatCompletionMessageParam dicts message_lists = [ [ {"role": "system", "content": "You are a helpful assistant."}, {"role": "user", "content": "What is 2+2?"}, {"role": "assistant", "content": "2+2 equals 4."} ], # ... more trajectories ] scores = await ruler( message_lists, "openai/o3" ) for score in scores: print(f"Trajectory {score.trajectory_id}: {score.score} - {score.explanation}") ``` ## Best Practices 1. **Clear system prompts**: RULER uses the system prompt to understand the agent's goal. Make sure your system prompts clearly describe what the agent should do. 2. **Group size**: Use 4-8 trajectories per group for optimal balance between diversity and cost. Very large groups are not recommended because they can confuse the judge. 3. **Debug mode**: Enable `debug=True` to see the judge's reasoning, which helps identify scoring patterns. 4. **Judge selection**: Cheaper models like Qwen3 32B often work well and are more cost-effective than larger models. ## Integration with Training RULER integrates into ART's training loop using the `gather_trajectory_groups` helper with an `after_each` callback: ```python import art from art.rewards import ruler_score_group # In your training loop groups = await art.gather_trajectory_groups( ( art.TrajectoryGroup( rollout(model, scenario) for _ in range(4) # 4 trajectories per group ) for scenario in batch_scenarios ), after_each=lambda group: ruler_score_group( group, "openai/o3", swallow_exceptions=True # Return None on error, filtering out the group ) ) # Train on the judged groups result = await backend.train(model, groups) await model.log(groups, metrics=result.metrics, step=result.step, split="train") ``` The `swallow_exceptions=True` parameter is recommended in production to handle judge API failures gracefully - groups that fail to be judged are simply filtered out rather than crashing the training loop. ## Combining RULER with Independent Rewards While not usually necessary, RULER can be easily combined with other reward functions that judge trajectories independently. You can calculate independent rewards before applying RULER during the rollout function, or calculate and combine them afterward. Either of these approaches allow you to combine hand-crafted rewards with RULER's general-purpose scoring. ### Preserving Original Rewards If you assign rewards within your rollout function, RULER preserves them under the "independent_reward" metric: ```python # Your trajectories already have rewards from rollout judged_group = await ruler_score_group(group, "openai/o3", debug=True) # Combine RULER scores with original rewards for traj in judged_group.trajectories: traj.reward += traj.metrics["independent_reward"] ``` ### Adding Independent Rewards After Judging Additionally, you can adjust rewards after calling `ruler_score_group`: ```python # Score with RULER first judged_group = await ruler_score_group(group, "openai/o3", debug=True) # Add your own scoring on top for traj in judged_group.trajectories: independent_reward = score(traj) # Your custom scoring function traj.reward += independent_reward ``` ## Performance Tips - **Caching**: RULER automatically caches judge responses to disk to avoid redundant API calls - **Batch processing**: Process multiple groups in parallel when possible - **Token efficiency**: Common prefixes are automatically deduplicated to save tokens ## Troubleshooting ### Low scores for all trajectories - Check that your system prompt clearly defines the task - Ensure trajectories are actually attempting the task - Try the default rubric before customizing ### Inconsistent rankings - Increase group size for more stable relative rankings - Use a more capable judge model - Add more specific criteria to your rubric ### High API costs - Use cheaper judge models (e.g., Qwen3 32B) - Reduce group size Since RULER uses LiteLLM under the hood, ART automatically suppresses harmless Pydantic serialization warnings from LiteLLM ([related issue](https://github.com/BerriAI/litellm/issues/11759)). To disable this behavior, set `SUPPRESS_LITELLM_SERIALIZATION_WARNINGS=0` in your environment. # SFT Training import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; **Supervised fine-tuning (SFT)** trains a model on labeled chat examples rather than through trial-and-error with rewards. It's useful for **distillation** (training a smaller model on outputs from a larger teacher model), **teaching a specific output style or format**, and **warming up** a model before RL training so it starts from a stronger baseline. ART supports SFT on both `LocalBackend` and `ServerlessBackend`. ## Data format SFT training data is a JSONL file where each line is a JSON object with `messages` and optionally `tools`. Here's a simple example: ```json { "messages": [ { "role": "system", "content": "You are a helpful assistant" }, { "role": "user", "content": "What is the capital of Tasmania?" }, { "role": "assistant", "content": "Hobart" } ] } ``` To train on tool-call conversations, include a `tools` array and `tool_calls` in the assistant message: ```json { "messages": [ { "role": "system", "content": "You are a helpful assistant" }, { "role": "user", "content": "What's the weather in Hobart?" }, { "role": "assistant", "content": null, "tool_calls": [ { "id": "call_1", "type": "function", "function": { "name": "get_weather", "arguments": "{\"location\": \"Hobart\"}" } } ] }, { "role": "tool", "tool_call_id": "call_1", "content": "15°C, partly cloudy" }, { "role": "assistant", "content": "It's currently 15°C and partly cloudy in Hobart." } ], "tools": [ { "type": "function", "function": { "name": "get_weather", "description": "Get current weather", "parameters": { "type": "object", "properties": { "location": { "type": "string" } } } } } ] } ``` Each line must follow these rules: - **`messages`** (required) — a non-empty list of chat messages. Each message has a `role` (`system`, `user`, `assistant`, or `tool`) and `content`. The last message **must** be from the `assistant` role. - **`tools`** (optional) — a list of tool/function definitions, following the [OpenAI tool format](https://platform.openai.com/docs/api-reference/chat). Messages follow the [OpenAI chat format](https://platform.openai.com/docs/api-reference/chat), including support for `tool_calls` in assistant messages. Only the assistant's response tokens contribute to the training loss. Instruction and user tokens are automatically masked so the model learns to produce better responses without memorizing prompts. ## Training from a JSONL file For large datasets, use `train_sft_from_file`. It handles batching and applies a learning rate schedule automatically. ```python import asyncio import art from art.local import LocalBackend # from art.serverless.backend import ServerlessBackend from art.utils.sft import train_sft_from_file async def main(): backend = LocalBackend() # backend = ServerlessBackend() # or use serverless for managed GPUs model = art.TrainableModel( name="my-sft-model", project="sft-project", base_model="Qwen/Qwen3-30B-A3B-Instruct-2507", ) await model.register(backend) await train_sft_from_file( model=model, file_path="data/train.jsonl", epochs=3, batch_size=2, peak_lr=2e-4, schedule_type="cosine", warmup_ratio=0.1, assistant_turns="last", verbose=True, ) asyncio.run(main()) ``` Set `assistant_turns="last"` to calculate loss only on the final assistant message in each JSONL row. Earlier assistant messages remain available as context. If omitted, the helper trains on all assistant turns. ## Distillation Distillation trains a smaller model on completions from a larger teacher model. Generate responses from the teacher, wrap them as trajectories, and fine-tune: ```python import asyncio from openai import AsyncOpenAI import art from art.local import LocalBackend # from art.serverless.backend import ServerlessBackend from art.utils.sft import create_sft_dataset_iterator TEACHER_MODEL = "z-ai/glm-5" async def main(): teacher_client = AsyncOpenAI( api_key="your-api-key", base_url="https://openrouter.ai/api/v1", ) # Small models often produce malformed JSON or miss fields. # Distilling from a larger model teaches consistent structured extraction. system_prompt = "Extract {name, role, company} as JSON from the text. Return only valid JSON." inputs = [ "Hi, I'm Sarah Chen, VP of Engineering at Acme Corp.", "David Park here — senior data scientist at Globex.", "I'm Maria Lopez. I lead product at Initech.", "Hey, this is James Wu from Umbrella Corp, working as a DevOps engineer.", "My name is Aisha Patel and I'm a research lead at DeepMind.", # ... more inputs ] trajectories = [] for text in inputs: messages = [ {"role": "system", "content": system_prompt}, {"role": "user", "content": text}, ] completion = await teacher_client.chat.completions.create( model=TEACHER_MODEL, messages=messages, ) trajectories.append(art.Trajectory( messages_and_choices=[ *messages, {"role": "assistant", "content": completion.choices[0].message.content}, ], )) # Train student model on teacher outputs backend = LocalBackend() # backend = ServerlessBackend() # or use serverless for managed GPUs student = art.TrainableModel( name="distillation-001", project="sft-distillation", base_model="Qwen/Qwen3-30B-A3B-Instruct-2507", ) await student.register(backend) # create_sft_dataset_iterator computes the LR schedule (warmup + decay) over # the full dataset, then slices it correctly across chunks. Each # chunk's train_sft call logs its own metrics, giving you granular # loss curves instead of a single aggregated number. for chunk in create_sft_dataset_iterator(trajectories, peak_lr=2e-4): await student.train_sft(chunk.trajectories, chunk.config) asyncio.run(main()) ``` ## SFT as warmup before RL A common pattern is to run SFT first to give the model a head start, then switch to RL for further improvement. ART supports switching between SFT and RL training seamlessly within the same run: ```python import art from art.local import LocalBackend # from art.serverless.backend import ServerlessBackend from art.utils.sft import train_sft_from_file async def main(): backend = LocalBackend() # backend = ServerlessBackend() # or use serverless for managed GPUs model = art.TrainableModel( name="warmup-then-rl", project="my-project", base_model="Qwen/Qwen3-30B-A3B-Instruct-2507", ) await model.register(backend) # Phase 1: SFT warmup from a dataset await train_sft_from_file( model=model, file_path="data/train.jsonl", epochs=3, ) # Phase 2: RL training picks up from the SFT checkpoint from my_project import rollout, scenarios for step in range(await model.get_step(), 50): train_groups = await art.gather_trajectory_groups( [ art.TrajectoryGroup(rollout(model, scenario) for _ in range(8)) for scenario in scenarios ] ) result = await backend.train(model, train_groups) await model.log(train_groups, metrics=result.metrics, step=result.step, split="train") ``` This works because both SFT and RL train the same LoRA adapter. After SFT completes, RL continues from the updated weights. ## Local vs Serverless Both backends support SFT with the same API. The key differences are in how training executes: | | LocalBackend | ServerlessBackend | | --------------- | ------------------------------------ | -------------------------------------------------- | | **Execution** | Trains on your local GPU | Sends data to remote managed GPUs | | **Checkpoints** | Saved as LoRA adapters in `.art/` | Stored as W&B Artifacts | | **Inference** | You deploy the LoRA adapter yourself | Production-ready inference endpoint out of the box | | **Best for** | Development, iteration, full control | Production, no local GPU, large-scale training | The `ServerlessBackend` requires a W&B API key. See the [backend docs](/fundamentals/art-backend) for setup instructions. ```python # Serverless — same API, training runs remotely from art.serverless.backend import ServerlessBackend backend = ServerlessBackend() # uses WANDB_API_KEY env var model = art.TrainableModel( name="my-sft-model", project="sft-project", base_model="Qwen/Qwen3-30B-A3B-Instruct-2507", ) await model.register(backend) await model.train_sft(trajectories, config=art.TrainSFTConfig(learning_rate=5e-5)) ``` # Checkpoint Forking import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; Checkpoint forking example Checkpoint forking allows you to create a new training run that starts from an existing model's checkpoint. This is particularly useful when: - Training has gone off track and you want to restart from a known good checkpoint - You want to experiment with different hyperparameters from a specific point - You need to branch off multiple experiments from the same checkpoint This feature is marked as experimental because we're still refining the API shape. However, the core functionality will remain stable. ## Basic Usage The simplest way to fork a checkpoint is to specify it when creating your model: ```python import art from art.local import LocalBackend async def train(): async with LocalBackend() as backend: # Create a new model that will fork from an existing checkpoint model = art.TrainableModel( name="my-model-v2", project="my-project", base_model="OpenPipe/Qwen3-14B-Instruct", ) # Copy the checkpoint from another model await backend._experimental_fork_checkpoint( model, from_model="my-model-v1", not_after_step=500, # Use checkpoint at or before step 500 verbose=True, ) # Register and continue training await model.register(backend) # ... rest of training code ``` ## Forking from S3 If your checkpoints are stored in S3, you can fork directly from there: ```python await backend._experimental_fork_checkpoint( model, from_model="my-model-v1", from_s3_bucket="my-backup-bucket", not_after_step=500, verbose=True, ) ``` ## Parameters ### `from_model` (required) The name of the model to fork from. ### `from_project` (optional) The project containing the model to fork from. Defaults to the current model's project. ### `from_s3_bucket` (optional) S3 bucket to pull the checkpoint from. If not provided, will look for the checkpoint locally. ### `not_after_step` (optional) The maximum step number to use. The function will use the latest checkpoint that is less than or equal to this step. If not provided, uses the latest available checkpoint. ### `verbose` (optional) Whether to print detailed progress information during the forking process. ## How It Works 1. **Checkpoint Selection**: The system finds the appropriate checkpoint based on your `not_after_step` parameter 2. **S3 Pull** (if needed): If forking from S3, only the specific checkpoint is downloaded, not the entire model history 3. **Checkpoint Copy**: The checkpoint is copied to your new model's directory at the same step number 4. **Training Continuation**: Your model can now continue training from this checkpoint ## Example: Lowering the Learning Rate Here's a practical example of using checkpoint forking to test a lower learning rate: ```python # Original model trained with lr=1e-5 base_model = art.TrainableModel( name="summarizer-base", project="experiments", base_model="OpenPipe/Qwen3-14B-Instruct", ) # Fork at step 1000 to try lower learning rate low_lr_model = art.TrainableModel( name="summarizer-low-lr", project="experiments", base_model="OpenPipe/Qwen3-14B-Instruct", ) async def experiment(): async with LocalBackend() as backend: # Fork the model from the base model await backend._experimental_fork_checkpoint( low_lr_model, from_model="summarizer-base", not_after_step=1000, verbose=True, ) await model.register(backend) # Now train with a lower learning rate # ... training code with different configs ``` ## Notes - Checkpoints are forked at the same step number they had in the source model - The `not_after_step` parameter uses `<=` comparison, so specifying 500 will include step 500 if it exists - Only checkpoint files are copied - training logs and trajectories are not included in the fork # Deleting Checkpoints import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; Training jobs can run for thousands of steps, and each step generates a new model checkpoint. For most training runs, these checkpoints are LoRAs that takes up 80-150MB of disk space. To reduce storage overhead and preserve only the best checkpoint from your runs, you can set up automatic deletion of all but your best-performing and most recent checkpoints. ## Deleting low-performing checkpoints To delete all but the most recent and best-performing checkpoints of a model, call the `delete_checkpoints` method as shown below. ```python import art # also works with LocalBackend from art.serverless.backend import ServerlessBackend model = art.TrainableModel( name="agent-001", project="checkpoint-deletion-demo", base_model="OpenPipe/Qwen3-14B-Instruct", ) backend = ServerlessBackend() # in order for the model to know where to look for its existing checkpoints, # we have to point it to the correct backend await model.register(backend) # deletes all but the most recent checkpoint # and the checkpoint with the highest val/reward await model.delete_checkpoints() ``` By default, `delete_checkpoints` ranks existing checkpoints by their `val/reward` score and erases all but the highest-performing and most recent. However, `delete_checkpoints` can be configured to use any metric that it is passed. ```python await model.delete_checkpoints(best_checkpoint_metric="train/eval_1_score") ``` Keep in mind that once checkpoints are deleted, they generally cannot be recovered, so use this method with caution. ## Deleting within a training loop Below is a simple example of a training loop that trains a model for 50 steps before exiting. By default, the LoRA checkpoint generated by each step will automatically be saved in the storage mechanism your backend uses (in this case W&B Artifacts). ```python import art from art.serverless.backend import ServerlessBackend from .rollout import rollout from .scenarios load_train_scenarios TRAINING_STEPS = 50 model = art.TrainableModel( name="agent-001", project="checkpoint-deletion-demo", base_model="OpenPipe/Qwen3-14B-Instruct", ) backend = ServerlessBackend() await model.register(backend) train_scenarios = load_train_scenarios() # training loop for _step in range(await model.get_step(), TRAINING_STEPS): train_groups = await art.gather_trajectory_groups( ( art.TrajectoryGroup(rollout(model, scenario, step) for _ in range(8)) for scenario in train_scenarios ), pbar_desc=f"gather(train:{step})", ) # trains model and persists each LoRA as a W&B Artifact # ~120MB per step result = await backend.train(model, train_groups, learning_rate=5e-5) await model.log(train_groups, metrics=result.metrics, step=result.step, split="train") # ~6GB of storage used by checkpoints ``` However, since each LoRA checkpoint generated by this training run is ~120MB, in total this training run will require ~6GB of storage for the model checkpoints alone. To reduce our storage overhead, let's implement checkpoint deletion on each step. ```python ... # training loop for _step in range(await model.get_step(), TRAINING_STEPS): train_groups = await art.gather_trajectory_groups( ( art.TrajectoryGroup(rollout(model, scenario, step) for _ in range(8)) for scenario in train_scenarios ), pbar_desc=f"gather(train:{step})", ) # trains model and persists each LoRA as a W&B Artifact # ~120MB per step result = await backend.train(model, train_groups, learning_rate=5e-5) await model.log(train_groups, metrics=result.metrics, step=result.step, split="train") # clear all but the most recent and best-performing checkpoint on the train/reward metric await model.delete_checkpoints(best_checkpoint_metric="train/reward") # ~240MB of storage used by checkpoints ``` With this change, we've reduced the total amount of storage used by checkpoints from 6GB to 240MB, while preserving the checkpoint that performed the best on `train/reward`. # Additional Histories import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; Additional histories allow you to include multiple separate conversation histories within a single trajectory. This powerful feature enables training of agents with non-linear conversation flows, such as agents that call sub-agents or compact their message history periodically. ## What are Additional Histories? In ART, a trajectory typically contains a single sequence of messages representing the agent's conversation. However, some advanced use cases require training on multiple related but separate conversations within the same trajectory context. The `additional_histories` feature addresses this need. Each trajectory can contain: - A primary `messages_and_choices` sequence (the main conversation) - An optional list of `additional_histories`, where each history contains its own `messages_and_choices` and optional `tools` ## Why Use Additional Histories? Note: for simplicity and ease of use, we've used normal "assistant" messages in the examples below. In reality, you'll want to use `Choice` objects to represent assistant messages that should be trained on, as seen in the example notebooks. ### 1. Preserving Special Tokens in Multi-Turn Conversations Some models, like Qwen 3, use chat templates that remove special tokens (such as ``) from previous turns in multi-turn conversations. This can interfere with training when you want the model to learn from its thinking process across all turns. ART-managed inference and SFT paths preserve prior-turn thinking by default when the model's chat template supports it. You can override that behavior explicitly with `chat_template_kwargs={"preserve_thinking": False}`. Additional histories remain useful for custom or externally managed templates that do not expose a prior-thinking preservation option. By splitting each turn into a separate history, you can preserve these tokens for training: ```python from art.trajectories import LegacyHistory, Trajectory # Instead of a single multi-turn conversation that loses tokens # Train as separate histories to preserve them trajectory = Trajectory( messages_and_choices=[ # First turn with thinking {"role": "user", "content": "What is 2+2?"}, {"role": "assistant", "content": "I need to add 2 and 24"} ], additional_histories=[ LegacyHistory( messages_and_choices=[ # The Qwen 3 chat template removes tokens from previous turns {"role": "user", "content": "What is 2+2?"}, {"role": "assistant", "content": "4"}, {"role": "user", "content": "What is 3+3?"}, {"role": "assistant", "content": "I need to add 3 and 36"} ] ) ] ) ``` ### 2. Training Agents That Call Sub-Agents When an agent delegates work to sub-agents, each sub-agent conversation can be stored as an additional history: ```python trajectory = Trajectory( # Main agent conversation messages_and_choices=[ {"role": "user", "content": "Analyze this codebase and fix any bugs"}, {"role": "assistant", "tool_calls": [ {"type": "function", "function": {"name": "analyze_code", "arguments": "Find potential bugs in main.py"}}, ]}, { "role": "tool", "tool_call_id": "...", "content": "Found 3 potential issues..." }, {"role": "assistant", "tool_calls": [ {"type": "function", "function": {"name": "fix_issues", "arguments": "Fix the null pointer issue on line 42 of main.py"}}, ]}, { "role": "tool", "tool_call_id": "...", "content": "Fixed by adding null check..." }, ], additional_histories=[ # Sub-agent 1: Code analysis LegacyHistory( messages_and_choices=[ {"role": "system", "content": "You are a code analysis expert"}, {"role": "user", "content": "Find potential bugs in main.py"}, {"role": "assistant", "content": "Found 3 potential issues..."} ] ), # Sub-agent 2: Bug fixing LegacyHistory( messages_and_choices=[ {"role": "system", "content": "You are a bug fixing expert"}, {"role": "user", "content": "Fix the null pointer issue on line 42"}, {"role": "assistant", "content": "Fixed by adding null check..."} ] ) ] ) ``` ### 3. History Compaction and Summarization For long-running agents that periodically compress their conversation history: ```python trajectory = Trajectory( # Current active conversation messages_and_choices=[ {"role": "system", "content": "You are a helpful assistant."}, {"role": "user", "content": "Explain quantum entanglement"}, {"role": "assistant", "content": "Quantum entanglement is..."}, # ... many more messages ... ], additional_histories=[ # Previous conversation segment before compaction LegacyHistory( messages_and_choices=[ {"role": "system", "content": "You are a helpful assistant."}, {"role": "user", "content": "Compacted conversation history: the user asked about quantum entanglement, and the assistant explained..."}, {"role": "user", "content": "Tell me more about the history of quantum entanglement"}, {"role": "assistant", "content": "Quantum entanglement was first..."}, ] ) ] ) ``` ## How It Works ### Tokenization Process When a trajectory with additional histories is tokenized: 1. The main history (from `messages_and_choices`) is tokenized first 2. Each additional history is tokenized separately 3. The training weight is distributed across all tokenized results 4. Each history maintains its own context and token boundaries ```python # In the tokenization pipeline histories = [create_history_from_trajectory(trajectory)] # Main history histories.extend(trajectory.additional_histories) # Add all additional histories # Each history is tokenized independently for history in histories: tokenized_result = tokenize_history(history) # Weight is distributed across all results ``` ### Data Structure The legacy `LegacyHistory` payload structure: ```python @dataclass class LegacyHistory: messages_and_choices: list[dict[str, Any]] tools: list[Tool] | None = None ``` The `Trajectory` class with additional histories: ```python @dataclass class Trajectory: messages_and_choices: list[dict[str, Any]] tools: list[Tool] | None = None additional_histories: list[LegacyHistory] = field(default_factory=list) reward: float | None = None metrics: dict[str, Any] = field(default_factory=dict) ``` ## Implementation Guide ### Creating a Trajectory with Additional Histories ```python from art.trajectories import LegacyHistory, Trajectory # Create the main conversation main_messages = [ {"role": "system", "content": "You are a helpful assistant"}, {"role": "user", "content": "Help me with a complex task"}, {"role": "assistant", "content": "I'll help you with that"} ] # Create additional histories history1 = LegacyHistory( messages_and_choices=[ {"role": "user", "content": "First subtask"}, {"role": "assistant", "content": "Completing first subtask..."} ] ) history2 = LegacyHistory( messages_and_choices=[ {"role": "user", "content": "Second subtask"}, {"role": "assistant", "content": "Completing second subtask..."} ] ) # Combine into a trajectory trajectory = Trajectory( messages_and_choices=main_messages, additional_histories=[history1, history2], reward=0.8, metrics={"task_completed": True} ) ``` ## Current Limitations The RULER reward function does not currently support trajectories with additional histories. If you attempt to use RULER with `additional_histories`, it will raise an error. Support for this feature in RULER is planned for a future release. ## Related Topics - [Models](/resources/models) - Model-specific considerations including Qwen 3 # Tracking Metrics import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; ART writes a metrics row every time you call `model.log(...)`. Those rows go to `history.jsonl` in the run directory and, if W&B logging is enabled, to W&B. Use this page for three things: - understand the metrics ART emits automatically - add task-specific metrics from your own rollout code - track external judge and API spend alongside training metrics ## What ART logs automatically When you call `await model.log(train_groups, split="train")` with trajectory groups and training metrics, ART logs most of the values you need to monitor a run. | Type | Examples | | --- | --- | | Reward | `train/reward`, `train/reward_std_dev`, `train/exception_rate`, `val/reward` | | Loss | `loss/train`, `loss/entropy`, `loss/kl_div`, `loss/grad_norm`, `loss/learning_rate` | | Data | `data/step_num_scenarios`, `data/step_num_trajectories`, `data/step_num_groups_submitted`, `data/step_num_groups_trainable` | | Time | `time/wall_clock_sec`, `time/step_wall_s`, `time/step_trainer_s` | | Cost | `costs/gpu` on `LocalBackend` when GPU pricing is known | If ART has the inputs it needs, it also derives: - cumulative metrics such as `time/cum/trainer_s`, `data/cum/num_unique_scenarios`, and `costs/cum/all` - cost rollups such as `costs/train`, `costs/eval`, and `costs/all` - throughput metrics such as `throughput/avg_trainer_tok_per_s` and `throughput/avg_actor_tok_per_s` Some metrics only appear when the backend or your code provides the underlying inputs. For example, `throughput/avg_actor_tok_per_s` requires both `data/step_actor_tokens` and `time/step_actor_s`. ## Add task-specific outcome metrics Attach metrics directly to each `Trajectory` when your rollout code knows whether an attempt succeeded, how many tools it called, or any other task-specific signal. ```python async def rollout(model: art.Model, scenario: Scenario) -> art.Trajectory: trajectory = art.Trajectory( messages_and_choices=[ {"role": "system", "content": SYSTEM_PROMPT}, {"role": "user", "content": scenario.prompt}, ], metadata={"scenario_id": scenario.id}, ) completion = await model.openai_client().chat.completions.create( model=model.get_inference_name(), messages=trajectory.messages(), ) trajectory.messages_and_choices.append(completion.choices[0]) trajectory.reward = score_reward(trajectory) trajectory.metrics["correct"] = float(is_correct(trajectory)) trajectory.metrics["tool_calls"] = float(count_tool_calls(trajectory)) return trajectory ``` On train steps, ART averages those rollout metrics and logs them under the `train/` namespace, such as `train/correct` and `train/tool_calls`. If you want to record one value per `TrajectoryGroup` instead of one per trajectory, pass `metrics={...}` when you build the group. ART logs those once per group, using keys like `train/group_difficulty` on train steps. ## Add step-level metrics ART cannot infer Use `model.metrics_builder()` for metrics that live outside individual trajectories, such as actor-side timing, token counts, or idle time. ```python builder = model.metrics_builder() with builder.measure("time/step_actor_s"): result = await run_rollouts() builder.add_data( step_num_scenarios=result.num_scenarios, step_actor_tokens=result.actor_tokens, scenario_ids=result.scenario_ids, ) builder.add_idle_times(step_actor_idle_s=result.actor_idle_s) await model.log(result.train_groups, split="train", step=result.step) ``` A few useful patterns: - log `scenario_ids` to unlock `data/cum/num_unique_scenarios` - log both `data/step_actor_tokens` and `time/step_actor_s` to unlock actor throughput metrics - log `time/step_eval_s` when eval runs happen outside the backend - use fully qualified keys like `time/step_actor_s` or `data/step_actor_tokens` for builder-managed metrics ART flushes builder-managed metrics on the next `model.log(...)` call. ## Track judge and API costs Use `@track_api_cost` when a function returns a provider response object with token usage. Wrap the relevant part of your code in a metrics context so ART knows whether the spend belongs to training or evaluation. ```python from art.metrics import track_api_cost @track_api_cost( source="llm_judge/correctness", provider="openai", model_name="openai/gpt-4.1", ) async def run_judge(client, messages): return await client.chat.completions.create( model="gpt-4.1", messages=messages, ) with model.metrics_builder("train").activate_context(): await run_judge(judge_client, train_messages) with model.metrics_builder("eval").activate_context(): await run_judge(judge_client, eval_messages) ``` The next metrics row will include: - `costs/train/llm_judge/correctness` or `costs/eval/llm_judge/correctness` - rollups such as `costs/train`, `costs/eval`, and `costs/all` - cumulative totals such as `costs/cum/all` ART can price OpenAI and Anthropic responses from their usage fields. You must pass both `provider` and `model_name` to `@track_api_cost`. For custom pricing or unsupported models, register pricing on the builder: ```python builder = model.metrics_builder() builder.register_model_pricing( "anthropic/my-custom-judge", prompt_per_million=1.2, completion_per_million=4.8, ) ``` ## Track GPU cost on LocalBackend `LocalBackend` can log `costs/gpu` automatically on train steps. ART currently auto-detects H200 pricing at `$3/hour` per GPU. For other hardware, pass an explicit override: ```python backend = LocalBackend(gpu_cost_per_hour_usd=2.25) ``` This lets ART include GPU spend in the same metrics stream as rewards, losses, and judge/API costs. # MCP•RL: Training Agents to Use MCP Servers import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; MCP•RL is a specialized application of ART that teaches language models to effectively use [Model Context Protocol (MCP) servers](https://modelcontextprotocol.io/). This approach enables you to train agents that can seamlessly interact with any MCP-compatible tool or service. ## What is MCP•RL? MCP•RL combines two powerful technologies: - **Model Context Protocol (MCP)**: A standard for connecting AI assistants to external tools and data sources - **ART (Agent Reinforcement Trainer)**: OpenPipe's framework for training better AI agents using reinforcement learning The result is a training pipeline that can automatically teach any language model to use MCP servers effectively, without requiring manually labeled training data. ## How MCP•RL Works The training process follows these key steps: ### 1. **Server Discovery** ```python # Query the MCP server to understand available tools tools_list = await mcp_client.list_tools() ``` ### 2. **Scenario Generation** ```python # Generate diverse training scenarios automatically from art.mcp import generate_scenarios scenario_collection = await generate_scenarios( tools=tools_list, num_scenarios=24, show_preview=True, generator_model="openai/gpt-4.1-mini", generator_api_key="your_openrouter_key", generator_base_url="https://openrouter.ai/api/v1", ) ``` ART automatically generates diverse training scenarios that exercise different aspects of the MCP server: simple single-tool usage, complex multi-step workflows, edge cases and error handling, and creative combinations of available tools. ### 3. **RULER Evaluation** ```python from art.rewards import ruler_score_group # RULER evaluates responses without labeled data scored_group = await ruler_score_group( group, judge_model="openai/o4-mini", ) ``` Instead of requiring human-labeled examples, RULER judges response quality by analyzing whether the agent accomplished the intended task, quality of tool usage, efficiency of the approach, and error handling. ### 4. **Reinforcement Learning** ```python # Train using RULER feedback groups = await gather_trajectory_groups( trajectory_groups_generator, pbar_desc="train gather step", ) scored_groups = [ await ruler_score_group( group, judge_model="openai/o4-mini", ) for group in groups ] result = await backend.train(model, scored_groups, learning_rate=1e-5) await model.log(scored_groups, metrics=result.metrics, step=result.step, split="train") ``` The model learns from RULER feedback using reinforcement learning, improving its ability to select appropriate tools, use correct parameters, chain tools effectively, and handle failures gracefully. ## Getting Started Optimizing against an MCP server can be surprisingly straightforward! ### Prerequisites - Access to an MCP server you want to train on - OpenRouter API key for training - Python environment with ART installed ### Basic Training Pipeline Here's a simplified example of training a model to use an MCP server: ```python import art from art.mcp import generate_scenarios from art.rewards import ruler_score_group from art import gather_trajectory_groups # Initialize the model model = art.TrainableModel( model="OpenPipe/Qwen3-14B-Instruct", openrouter_api_key="your_openrouter_key" ) # Generate training scenarios automatically scenario_collection = await generate_scenarios( tools=tools_list, resources=resources_list, num_scenarios=100, show_preview=False, generator_model="gpt-4o-mini", generator_api_key="your_openrouter_key", ) # Gather trajectory groups groups = await gather_trajectory_groups( ( art.TrajectoryGroup( rollout(model, scenario, False) for _ in range(4) # rollouts per group ) for scenario in scenario_collection ), pbar_desc="train gather step", ) # Score groups using RULER scored_groups = [ await ruler_score_group( group, judge_model="gpt-4o-mini", debug=True, swallow_exceptions=True ) for group in groups ] # Train the model result = await backend.train(model, scored_groups, learning_rate=1e-5) await model.log(scored_groups, metrics=result.metrics, step=result.step, split="train") ``` ### Example Use Cases - **Database Agent**: Train a model to query databases, understand schemas, and generate appropriate SQL commands via an MCP database server. - **File Management Agent**: Teach an agent to navigate file systems, read/write files, and perform complex file operations through an MCP file server. - **API Integration Agent**: Train models to interact with REST APIs, handle authentication, and process responses via MCP API wrappers. - **Development Tools Agent**: Create agents that can use development tools like Git, package managers, or testing frameworks through MCP servers. ## What MCP•RL is Good At MCP•RL excels at training agents to effectively use MCP servers by: - **Tool Usage**: Teaching when and how to use specific tools with appropriate parameters - **Multi-Step Workflows**: Chaining tool calls and interpreting outputs to build complex workflows - **Domain Adaptation**: Learning specialized terminology and conventions for different server types ## Best Practices - 📈 **Iterative Training** - Use checkpoint forking to experiment with different training approaches and parameters. - 🔍 **Monitor RULER Scores** - Pay attention to RULER evaluation metrics to understand where your agent excels and where it needs improvement. - 🧪 **Test Thoroughly** - Validate your trained agent on held-out scenarios that weren't used during training. - 📊 **Use Diverse Scenarios** - Ensure your training data covers the full range of tasks your agent will encounter in production. ## Troubleshooting ### Common Issues **Low RULER Scores**: - Check if your MCP server is responding correctly - Verify that generated scenarios are appropriate for your use case - Consider adjusting training parameters **Tool Selection Errors**: - Ensure the model has seen diverse examples of when to use each tool - Add more training scenarios that require careful tool selection **Parameter Issues**: - Include scenarios that demonstrate correct parameter usage - Consider adding validation examples to your training data ## Next Steps - Explore the [complete MCP•RL notebook](https://colab.research.google.com/github/openpipe/art-notebooks/blob/main/examples/mcp-rl/mcp-rl.ipynb) - Learn more about [RULER evaluation](/fundamentals/ruler) - Check out [checkpoint forking](/features/checkpoint-forking) for iterative training - Join our [Discord](https://discord.gg/zbBHRUpwf4) to discuss MCP•RL with the community MCP•RL is particularly effective because RULER can judge response quality purely from the agent's final output—no labeled data required! This makes it possible to train high-quality MCP agents with minimal manual intervention. # 🦜🔗 LangGraph import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; # LangGraph Integration ART's LangGraph integration enables you to build sophisticated, multi-step AI agents that learn and improve through reinforcement training. By combining LangGraph's powerful agent framework with ART's training capabilities, you can create agents that reason, use tools, and adapt their behavior over time. ## Installation To use ART with LangGraph, install ART with the required extras: ```bash uv pip install -U openpipe-art[backend,langgraph]>=0.4.9 ``` The `langgraph` extra includes the LangGraph integration dependencies, while `backend` provides the training backend components. ## Why Use ART with LangGraph? LangGraph provides an excellent framework for building various types of agents - from ReAct-style reasoning agents to complex multi-agent workflows with supervisor patterns and parallel execution. However, getting these agents to perform optimally often requires extensive prompt engineering and manual tuning. ART's integration with LangGraph addresses this by: - **Automatic behavior improvement**: Train your agents to get better at multi-step reasoning without manual prompt tuning - **Tool usage optimization**: Learn when and how to use tools more effectively through reinforcement learning - **Adaptive decision making**: Agents learn to make better choices about which actions to take in different situations - **Scalable training**: Train on diverse scenarios to build robust, generalizable agent behaviors ## Key Features - **Seamless integration**: Drop-in replacement for LangGraph's LLM initialization - **Automatic logging**: Captures all agent interactions for training data generation - **Multi-step trajectory support**: Handles complex agent workflows with tool calls and reasoning steps - **RULER compatibility**: Use ART's general-purpose reward function to train agents without hand-crafted rewards ## Code Examples Here are easily readable code snippets demonstrating the LangGraph integration functionality: ### Basic Setup and Initialization ```python import uuid import weave from langchain_core.messages import HumanMessage, SystemMessage from langchain_core.tools import tool from langgraph.prebuilt import create_react_agent from art.langgraph import init_chat_model import art # Initialize Weave tracking (optional) if os.getenv("WANDB_API_KEY", ""): weave.init(model.project, settings={"print_call_link": False}) ``` ### Defining Tools for Your Agent ```python @tool def search_inbox_tool(keywords: list[str]) -> list[dict]: """Search the inbox for emails matching the given keywords and return a list of dictionaries so the LLM can easily consume them.""" results = search_emails( inbox=scenario.inbox_address, keywords=keywords, sent_before=scenario.query_date, ) return [asdict(result) for result in results] @tool def read_email_tool(message_id: str) -> dict | None: """Read a specific email by message ID.""" email = read_email(message_id) if email: return email.model_dump() return None @tool def return_final_answer_tool(answer: str, reference_message_ids: list[str]) -> dict: """Return the final answer and the message IDs used to generate the answer.""" nonlocal final_answer final_answer = FinalAnswer(answer=answer, source_ids=reference_message_ids) return final_answer.model_dump() ``` ### Creating and Running a LangGraph ReAct Agent ```python @weave.op async def rollout(model: art.Model, email_scenario: EmailScenario) -> ProjectTrajectory: # Initialize chat model with temperature chat_model = init_chat_model(model.get_inference_name(), temperature=1.0) # Define available tools tools = [search_inbox_tool, read_email_tool, return_final_answer_tool] # Create the LangGraph ReAct agent react_agent = create_react_agent(chat_model, tools) # Configure agent execution config = { "configurable": {"thread_id": str(uuid.uuid4())}, "recursion_limit": MAX_TURNS, } # Run the agent with system and user messages await react_agent.ainvoke( { "messages": [ SystemMessage(content=system_prompt), HumanMessage(content=scenario.question), ] }, config=config, ) ``` ### Trajectory Tracking and Scoring ```python class ProjectTrajectory(art.Trajectory): final_answer: FinalAnswer | None = None # Create trajectory with metadata traj = ProjectTrajectory( reward=0.0, messages_and_choices=[], metadata={ "scenario_id": scenario.id, "step": email_scenario.step, }, ) # Score the trajectory using correctness judge if final_answer: traj.final_answer = final_answer correctness_judge_response = await judge_correctness( scenario, traj.final_answer.answer ) traj.metrics["correct"] = correctness_judge_response.accept ``` ### Training Loop with LangGraph Integration ```python from art.langgraph import wrap_rollout # Training configuration training_config = { "groups_per_step": 2, "num_epochs": 20, "rollouts_per_group": 4, "learning_rate": 1e-5, "max_steps": 20, } # Create trajectory groups for training for batch in training_iterator: groups = [] for scenario in batch.items: groups.append( art.TrajectoryGroup( ( wrap_rollout(model, rollout)( model, EmailScenario(step=batch.step, scenario=scenario) ) for _ in range(training_config["rollouts_per_group"]) ) ) ) # Gather trajectory groups finished_groups = await art.gather_trajectory_groups( groups, pbar_desc="gather", max_exceptions=training_config["rollouts_per_group"] * len(batch.items), ) # Apply RULER scoring judged_groups = [] for group in finished_groups: judged_group = await ruler_score_group(group, "openai/o4-mini") judged_groups.append(judged_group) # Train the model result = await backend.train( model, judged_groups, learning_rate=training_config["learning_rate"], logprob_calculation_chunk_size=8, ) await model.log(judged_groups, metrics=result.metrics, step=result.step, split="train") ``` ### Correctness Evaluation ```python from pydantic import BaseModel, Field from tenacity import retry, stop_after_attempt class CorrectnessJudgeResponse(BaseModel): reasoning: str = Field(description="Explanation of the reasoning process.") accept: bool = Field(description="Whether the AI answer should be accepted.") @retry(stop=stop_after_attempt(3)) async def judge_correctness(scenario: Scenario, answer: str) -> CorrectnessJudgeResponse: system_prompt = """ You are given a question, the reference answer, and an answer generated by an AI assistant. Your task is to decide whether the AI answer is correct and should be accepted. """ messages = [ {"role": "system", "content": system_prompt}, { "role": "user", "content": ( f"Question: {scenario.question}\n" f"Reference answer: {scenario.answer}\n" f"AI answer: {answer}" ), }, ] response = await acompletion( model="openai/gpt-4.1", messages=messages, response_format=CorrectnessJudgeResponse, ) return CorrectnessJudgeResponse.model_validate_json( response.choices[0].message.content or "{}" ) ``` ### Key Components Summary 1. **LangGraph ReAct Agent**: Uses `create_react_agent()` with custom tools and chat model 2. **Tool Definition**: Custom tools decorated with `@tool` for specific functionality 3. **Trajectory Tracking**: Custom trajectory class extends `art.Trajectory` 4. **Training Integration**: Uses `wrap_rollout()` and `art.gather_trajectory_groups()` 5. **Evaluation**: Automated correctness judging with retry logic 6. **Configuration**: Flexible training parameters and agent limits ## Complete Email Agent Example Here's a complete, runnable example that demonstrates training a LangGraph email search agent: ```python import asyncio import uuid from dataclasses import asdict from textwrap import dedent from typing import List import art import weave from langchain_core.messages import HumanMessage, SystemMessage from langchain_core.tools import tool from langgraph.prebuilt import create_react_agent from litellm import acompletion from pydantic import BaseModel, Field from tenacity import retry, stop_after_attempt from art.langgraph import init_chat_model, wrap_rollout from art.local import LocalBackend from art.utils import iterate_dataset # Initialize model and backend model = art.Model(name="Qwen/Qwen2.5-7B-Instruct") backend = LocalBackend() # Data models class EmailResult(BaseModel): message_id: str subject: str from_address: str date: str snippet: str class FinalAnswer(BaseModel): answer: str source_ids: List[str] class Scenario(BaseModel): id: str question: str answer: str inbox_address: str query_date: str class EmailScenario(BaseModel): step: int scenario: Scenario class ProjectTrajectory(art.Trajectory): final_answer: FinalAnswer | None = None class CorrectnessJudgeResponse(BaseModel): reasoning: str = Field(description="Explanation of the reasoning process.") accept: bool = Field(description="Whether the AI answer should be accepted.") # Mock email functions (replace with real implementation) def search_emails(inbox: str, keywords: List[str], sent_before: str) -> List[EmailResult]: """Mock email search function - replace with real implementation""" return [ EmailResult( message_id="msg_123", subject=f"Subject matching {keywords[0]}", from_address="sender@example.com", date="2024-01-15", snippet=f"Email snippet containing {keywords[0]}" ) ] def read_email(message_id: str) -> EmailResult | None: """Mock email read function - replace with real implementation""" return EmailResult( message_id=message_id, subject="Full email subject", from_address="sender@example.com", date="2024-01-15", snippet="Full email content here..." ) # Correctness evaluation @retry(stop=stop_after_attempt(3)) async def judge_correctness(scenario: Scenario, answer: str) -> CorrectnessJudgeResponse: system_prompt = dedent(""" You are given a question, the reference answer, and an answer generated by an AI assistant. Your task is to decide whether the AI answer is correct and should be accepted. """) messages = [ {"role": "system", "content": system_prompt}, { "role": "user", "content": ( f"Question: {scenario.question}\n" f"Reference answer: {scenario.answer}\n" f"AI answer: {answer}" ), }, ] response = await acompletion( model="openai/gpt-4o-mini", messages=messages, response_format=CorrectnessJudgeResponse, ) return CorrectnessJudgeResponse.model_validate_json( response.choices[0].message.content or "{}" ) # Main rollout function @weave.op async def rollout(model: art.Model, email_scenario: EmailScenario) -> ProjectTrajectory: scenario = email_scenario.scenario MAX_TURNS = 10 traj = ProjectTrajectory( reward=0.0, messages_and_choices=[], metadata={ "scenario_id": scenario.id, "step": email_scenario.step, }, ) system_prompt = dedent(f""" You are an email search agent. Use the tools to search emails and find answers. User's email address: {scenario.inbox_address} Today's date: {scenario.query_date} When you find the answer, use return_final_answer_tool with the answer and source message IDs. """) final_answer = None @tool def search_inbox_tool(keywords: List[str]) -> List[dict]: """Search inbox for emails matching keywords""" results = search_emails(scenario.inbox_address, keywords, scenario.query_date) return [asdict(result) for result in results] @tool def read_email_tool(message_id: str) -> dict | None: """Read a specific email by message ID""" email = read_email(message_id) return email.model_dump() if email else None @tool def return_final_answer_tool(answer: str, reference_message_ids: List[str]) -> dict: """Return final answer with source message IDs""" nonlocal final_answer final_answer = FinalAnswer(answer=answer, source_ids=reference_message_ids) return final_answer.model_dump() tools = [search_inbox_tool, read_email_tool, return_final_answer_tool] chat_model = init_chat_model(model.get_inference_name(), temperature=1.0) react_agent = create_react_agent(chat_model, tools) try: config = { "configurable": {"thread_id": str(uuid.uuid4())}, "recursion_limit": MAX_TURNS, } await react_agent.ainvoke({ "messages": [ SystemMessage(content=system_prompt), HumanMessage(content=scenario.question), ] }, config=config) if final_answer: traj.final_answer = final_answer correctness_judge_response = await judge_correctness(scenario, final_answer.answer) traj.metrics["correct"] = float(correctness_judge_response.accept) except Exception as e: print(f"Error running agent: {e}") traj.messages_and_choices.append({"role": "assistant", "content": f"Error: {str(e)}"}) return traj # Main training function async def main(): # Sample training scenarios (replace with real data) training_scenarios = [ Scenario( id="1", question="Find emails about the quarterly budget", answer="Budget meeting scheduled for Q4 review", inbox_address="user@company.com", query_date="2024-01-20" ), Scenario( id="2", question="Look for urgent project updates", answer="Project deadline moved to next month", inbox_address="user@company.com", query_date="2024-01-20" ), ] # Register model with backend await model.register(backend) # Training configuration training_config = { "groups_per_step": 2, "num_epochs": 3, "rollouts_per_group": 4, "learning_rate": 1e-5, "max_steps": 5, } # Training iterator training_iterator = iterate_dataset( training_scenarios, groups_per_step=training_config["groups_per_step"], num_epochs=training_config["num_epochs"], initial_step=await model.get_step(), ) # Training loop for batch in training_iterator: print(f"Training step {batch.step}, epoch {batch.epoch}") # Create trajectory groups groups = [] for scenario in batch.items: groups.append( art.TrajectoryGroup([ wrap_rollout(model, rollout)( model, EmailScenario(step=batch.step, scenario=scenario) ) for _ in range(training_config["rollouts_per_group"]) ]) ) # Gather trajectories finished_groups = await art.gather_trajectory_groups( groups, pbar_desc="gather", max_exceptions=training_config["rollouts_per_group"] * len(batch.items), ) # Apply RULER scoring judged_groups = [] for group in finished_groups: judged_group = await ruler_score_group(group, "openai/o4-mini") judged_groups.append(judged_group) # Train model result = await backend.train( model, judged_groups, learning_rate=training_config["learning_rate"], ) await model.log(judged_groups, metrics=result.metrics, step=result.step, split="train") print(f"Completed training step {batch.step}") if batch.step >= training_config["max_steps"]: break if __name__ == "__main__": asyncio.run(main()) ``` This complete example shows how to: 1. **Set up the environment** with model, backend, and data structures 2. **Define custom tools** for email search and retrieval 3. **Create a LangGraph ReAct agent** with proper configuration 4. **Implement trajectory tracking** with custom reward scoring 5. **Run the full training loop** with proper error handling 6. **Use wrap_rollout** to automatically capture agent interactions To use this example, simply replace the mock email functions (`search_emails`, `read_email`) with your actual email API integration, and provide real training scenarios in the `training_scenarios` list. ## Troubleshooting ### Common Issues **Empty trajectories or no training data captured:** - Ensure you're using `init_chat_model(model.get_inference_name())` in your rollout function - Verify your rollout function actually executes the agent and makes LLM calls - Check that `init_chat_model()` is called before creating your LangGraph agent **Import errors:** - Install ART with the correct extras: `uv pip install -U openpipe-art[backend,langgraph]>=0.4.9` - Ensure you have the required LangGraph dependencies **Training not starting:** - Verify you have trajectory data with `await art.gather_trajectory_groups(...)` - Check that the model is properly registered with `await model.register(backend)` ## Best Practices ### Agent Design - **Clear tool descriptions**: Ensure your tool functions have descriptive docstrings - **Error handling**: Include proper error handling in your tools for robust training - **Final answer pattern**: Use a dedicated tool for returning final answers to users ### Training Data - **Diverse scenarios**: Create varied training scenarios that cover different use cases - **Realistic complexity**: Include both simple and complex multi-step tasks - **Edge cases**: Add scenarios that test error handling and edge cases ### Performance Optimization - **Tool efficiency**: Optimize tool execution time since it affects training speed - **Batch generation**: Generate multiple trajectories efficiently using async patterns - **Resource management**: Monitor memory usage during long training runs The ART-LangGraph integration makes it straightforward to build and train sophisticated AI agents that improve their performance over time, turning your prototype agents into production-ready intelligent systems. # 🌍 OpenEnv import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; # OpenEnv Integration [OpenEnv](https://github.com/meta-pytorch/OpenEnv) provides a standard for interacting with agentic execution environments via simple Gymnasium-style APIs, making it easy to create reproducible training scenarios for code generation, tool usage, and other complex tasks. Because ART is unopinionated about the shape of your environment and rollout function, integration with OpenEnv is automatic - you can use any OpenEnv environment with ART without any special adapters or configuration. ## Code Example Here's a complete example showing how to train an agent using OpenEnv's echo environment with ART: ```python import asyncio from datetime import datetime import art from art.serverless.backend import ServerlessBackend from dotenv import load_dotenv from envs.echo_env import EchoAction, EchoEnv import weave PROMPT = "Use at most 100 tokens; maximize the total character length of the output." NUM_STEPS = 50 ROLLOUTS_PER_GROUP = 4 # The rollout function defines how your agent interacts with the environment async def rollout(model: art.TrainableModel, env_client: EchoEnv) -> art.Trajectory: # Reset the environment to get initial state await asyncio.to_thread(env_client.reset) # Create a trajectory to store interactions and rewards traj = art.Trajectory( messages_and_choices=[{"role": "system", "content": PROMPT}], reward=0.0 ) # Use the model to generate an action choice = ( await model.openai_client().chat.completions.create( model=model.inference_model_name, messages=traj.messages(), max_completion_tokens=100, timeout=30, ) ).choices[0] reply = (choice.message.content or "").strip() # Send the action to the environment and get observation/reward result = await asyncio.to_thread( env_client.step, EchoAction(message=reply) ) # Record the model's output and reward traj.messages_and_choices.append(choice) traj.reward = result.reward return traj.finish() async def main() -> None: load_dotenv() weave.init("openenv-demo") # Set up the training backend backend = ServerlessBackend() # Define the model to train model = art.TrainableModel( name=f"openenv-echo-{datetime.now().strftime('%Y-%m-%d-%H%M%S')}", project="openenv-demo", base_model="OpenPipe/Qwen3-14B-Instruct", ) await model.register(backend) # Create a pool of environment clients for efficient training env_pool = [ EchoEnv.from_docker_image("quixote13/echo-env:latest") for _ in range(ROLLOUTS_PER_GROUP) ] # Training loop for step in range(await model.get_step(), NUM_STEPS): print(f"Gathering groups for step {step}") # Run multiple rollouts in parallel groups = await art.gather_trajectory_groups([ art.TrajectoryGroup( rollout(model, env_client) for env_client in env_pool ) ]) # Train the model on collected trajectories result = await backend.train(model, groups) await model.log(groups, metrics=result.metrics, step=result.step, split="train") if __name__ == "__main__": asyncio.run(main()) ``` # Summarizer Tutorial import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; Most SOTA models are already trained to condense long documents into short summaries. However, not every summary is created equal. In this tutorial, we're going to train a summarizer that excels at filtering useful information from a document and cutting out the fluff. To skip ahead and see the results of a prior training run, check out the [blog post](https://openpipe.ai/blog/summary-rl). Otherwise, please enjoy this tutorial! Reading time: 45 min Training time: 4 hours Total cost: $22 ## Step 1: Clone the starter repo and install dependencies To get started, clone [Summary-RL](https://github.com/OpenPipe/Summary-RL/), which contains the following pieces of our RL pipeline: - The agent's environment - The reward function - Some training examples Once the repository is cloned, install dependencies. If you haven't already, install `uv` by following the instructions [here](https://docs.astral.sh/uv/getting-started/installation/). Then install the project dependencies by running `uv sync`. ### 2. Install backend dependencies and provision a GPU You'll be using `LocalBackend` to manage the GPU that your model will be trained on. Install ART with the backend dependencies: ```bash pip install openpipe-art[backend] ``` Make sure you have access to a machine with a modern NVIDIA GPU. This can be your local workstation or a cloud VM. If you're using a cloud provider (e.g. RunPod, Lambda, or GCP), launch the GPU instance and run the rest of this tutorial on that machine. ### 3. Set up optional environment variables found in `.env.example`. In a new `.env` file at the root of the repository, set the following optional environment variables: - `WANDB_API_KEY` - Enables metric logging to Weights & Biases. - `OPENPIPE_API_KEY` - Enables chat completion logging to OpenPipe. - `OPENAI_API_KEY` - Will be necessary for later comparison benchmarks, but not used for training. To enable model and logging backup to S3, you'll also need to provide AWS credentials. These are necessary for generating the benchmarks found in the `benchmarks` directory, but not for training itself. If you don't already have AWS credentials with create/read/write permissions for s3 buckets, follow the instructions [here](https://github.com/OpenPipe/Summary-RL/blob/main/CONFIGURING_AWS.md). - `AWS_ACCESS_KEY_ID` - Your AWS access key ID, which should have create/read/write permissions for s3 buckets. - `AWS_SECRET_ACCESS_KEY` - Your matching secret access key. - `AWS_REGION` - The region of the S3 bucket. - `BACKUP_BUCKET` - The name of the S3 bucket in which to store model checkpoints and logging data. Can be a new bucket or an existing one. ### 4. Run the training script ```bash uv run python src/summarizer/train.py ``` The first training run will: - Register the model with ART. - Download the model checkpoint from S3 (if configured). - Start vLLM and the training service on your GPU. - Train the model for a specified number of steps. - Upload the final model checkpoint to S3 (if configured). ### 5. Shutting down your GPU instance When you're done training and running benchmarks, shut down your GPU instance through your cloud provider's console or CLI. If you're running locally, you can simply stop the training process. ### Running Benchmarks The `benchmark_models.py` script will compare the performance of the trained model to `gpt-4o`, `gpt-4.1`, `o4-mini`, and `gemini-2.5-pro-preview`. Before running the benchmark script, make sure you've provided a valid `OPENROUTER_API_KEY` and the AWS credentials detailed in step 3. These credentials are necessary for the script to upload the benchmark results to S3. ```bash uv run python benchmarks/benchmark_models.py ``` This script will: - Run each benchmarked model through each document in the validation set. - Record the percentage of questions that each model's summary allowed Gemini 2.5 Flash to answer correctly. - Upload the results to S3. Once the benchmark generation script has finished running, you can view the results and generate visual charts by navigating to `benchmarks/display_benchmarks.ipynb` and running the cells. After running all the cells, you should see something like the following: Benchmark Percentage of Questions Answered Comparison _The percentage of questions that each model's summary allowed Gemini 2.5 Flash to answer correctly at each training step. By step 40 of this training run, the trained model outperforms every other model._ Benchmark Percentage of Questions Answered Comparison _A side-by-side comparison of the percentage of questions that each model's summary allowed Gemini 2.5 Flash to answer correctly. The trained model began with a percentage of 37%, but by the final step, it was able to generate summaries that allowed Gemini 2.5 Flash to answer 70% of the questions correctly._ # Open Deep Research Tutorial import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; This tutorial demonstrates how to train your own deep research agent using GRPO to exceed Sonnet 4's perfromance. Specifically, you will be using the [ART](https://github.com/OpenPipe/ART) library to specialize Qwen2.5 14B for [Langchain's open deep research](https://github.com/langchain-ai/open_deep_research) framework, and will evaluate your agent's performance using [DeepResearch Bench: A Comprehensive Benchmark for Deep Research Agents](https://github.com/Ayanami0730/deep_research_bench). In addition to the GRPO training step, you will also run an initial SFT training run to improve the model's baseline performance. Checkpoint forking example Reading time: 45 min Training time: 30 hr Total cost: ~$350 ### Step 1: Clone the starter repo and install dependencies To get started, clone [Open Deep Research Training](https://github.com/OpenPipe/open_deep_research_training), which contains the following pieces of our RL pipeline: - The deep research agent environment - The reward function based on DeepResearch Bench - SFT and GRPO training scripts - Evaluation benchmarks Once the repository is cloned, install dependencies. If you haven't already, install `uv` by following the instructions [here](https://docs.astral.sh/uv/getting-started/installation/). Then install the project dependencies by running `uv sync`. ### Step 2: Install backend dependencies and provision a GPU You'll be using `LocalBackend` to manage the GPU that your model will be trained on. Install ART with the backend dependencies: ```bash pip install openpipe-art[backend] ``` Make sure you have access to a machine with one or more modern NVIDIA GPUs. This can be your local workstation or a cloud VM. If you're using a cloud provider, launch the GPU instance and run the rest of this tutorial on that machine. ### Step 3: Set up optional environment variables found in `.env.example` Copy `.env.example` to `.env` at the root of the repository, and fill in the values for the environment variables. If you're unsure about any of the values, refer to [ENV_INSTRUCTIONS.md](https://github.com/OpenPipe/open_deep_research_training/blob/main/ENV_INSTRUCTIONS.md). ### Step 4: Run the training scripts You'll want to run these scripts in this order: ```bash uv run collect_sft.py # Collect samples for your sft training run. ~1 Hour ``` This script collects supervised fine-tuning data by running the research agent on a subset of the DeepResearch Bench dataset. The collected trajectories will be used to improve the model's baseline performance before RL training. ```bash uv run run_sft.py # Run your sft training run. ~1 Hour ``` The SFT training step improves the model's ability to follow the research agent format and reasoning patterns. This creates a better starting point for the subsequent RL training. ```bash uv run run_train.py # Run your rl training run. 1+ Day ``` This is the main GRPO training loop where the model learns to optimize its research strategies based on feedback from the DeepResearch Bench evaluation framework. The first training run will: - **Spin up a cluster with 1 or more H200 GPUs.** - This usually takes about 10 minutes, but RunPod occasionally has network throughput issues that can cause the cluster to take up to 30 minutes to spin up. - **Register the model with ART.** - This usually takes less than 5 minutes, though it can require up to 30 minutes if RunPod experiences network issues. - **Download the model checkpoint.** - Usually takes a few minutes depending on the model size. - **Train the model for a specified number of steps.** - Each RL step involves running the research agent on a subset of benchmark questions, and updating the model based on the rewards. We hold out another randomly-selected subset of 10 questions (10% of the total benchmark) that are never used in training that we run evaluations on every 10 steps to make sure the model is still making progress. Training time depends on the number of steps and the complexity of each research task. - **Upload the final model checkpoint.** - This usually takes a few minutes. ### Step 5: Generate the benchmarks Run the benchmark script to evaluate your trained models: ```bash uv run evaluate/benchmark_model.py ``` This script will: - Run each benchmarked model through the DeepResearch Bench evaluation - Compare performance against baseline models (GPT-4.1, Sonnet 4, etc.) - Generate accuracy metrics and detailed results Then run the `display_benchmarks.ipynb` notebook to visualize the results and generate comparison charts. ### Step 6: Shutting down your GPU instance When you're done training and running benchmarks, shut down your GPU instance through your cloud provider's console or CLI. If you're running locally, you can stop the training process. ## Training Results After completing the full training pipeline, you should see results similar to the chart at the beginning of this tutorial. The trained model typically shows: - Improved accuracy on research questions compared to the base model - Better structured research approaches - More comprehensive information gathering - Higher quality synthesis of research findings The benchmark comparison will show how your trained model performs relative to leading commercial models like GPT-4.1 and Sonnet 4. ## Next Steps Your model is trained and portable! Upload it to any platform you choose, including HuggingFace and inference providers like Together and Fireworks. To learn more about ART, check out another tutorial or look through our notebooks! As always, the [ART Discord](https://discord.gg/zbBHRUpwf4) is a great place to ask questions and share results!
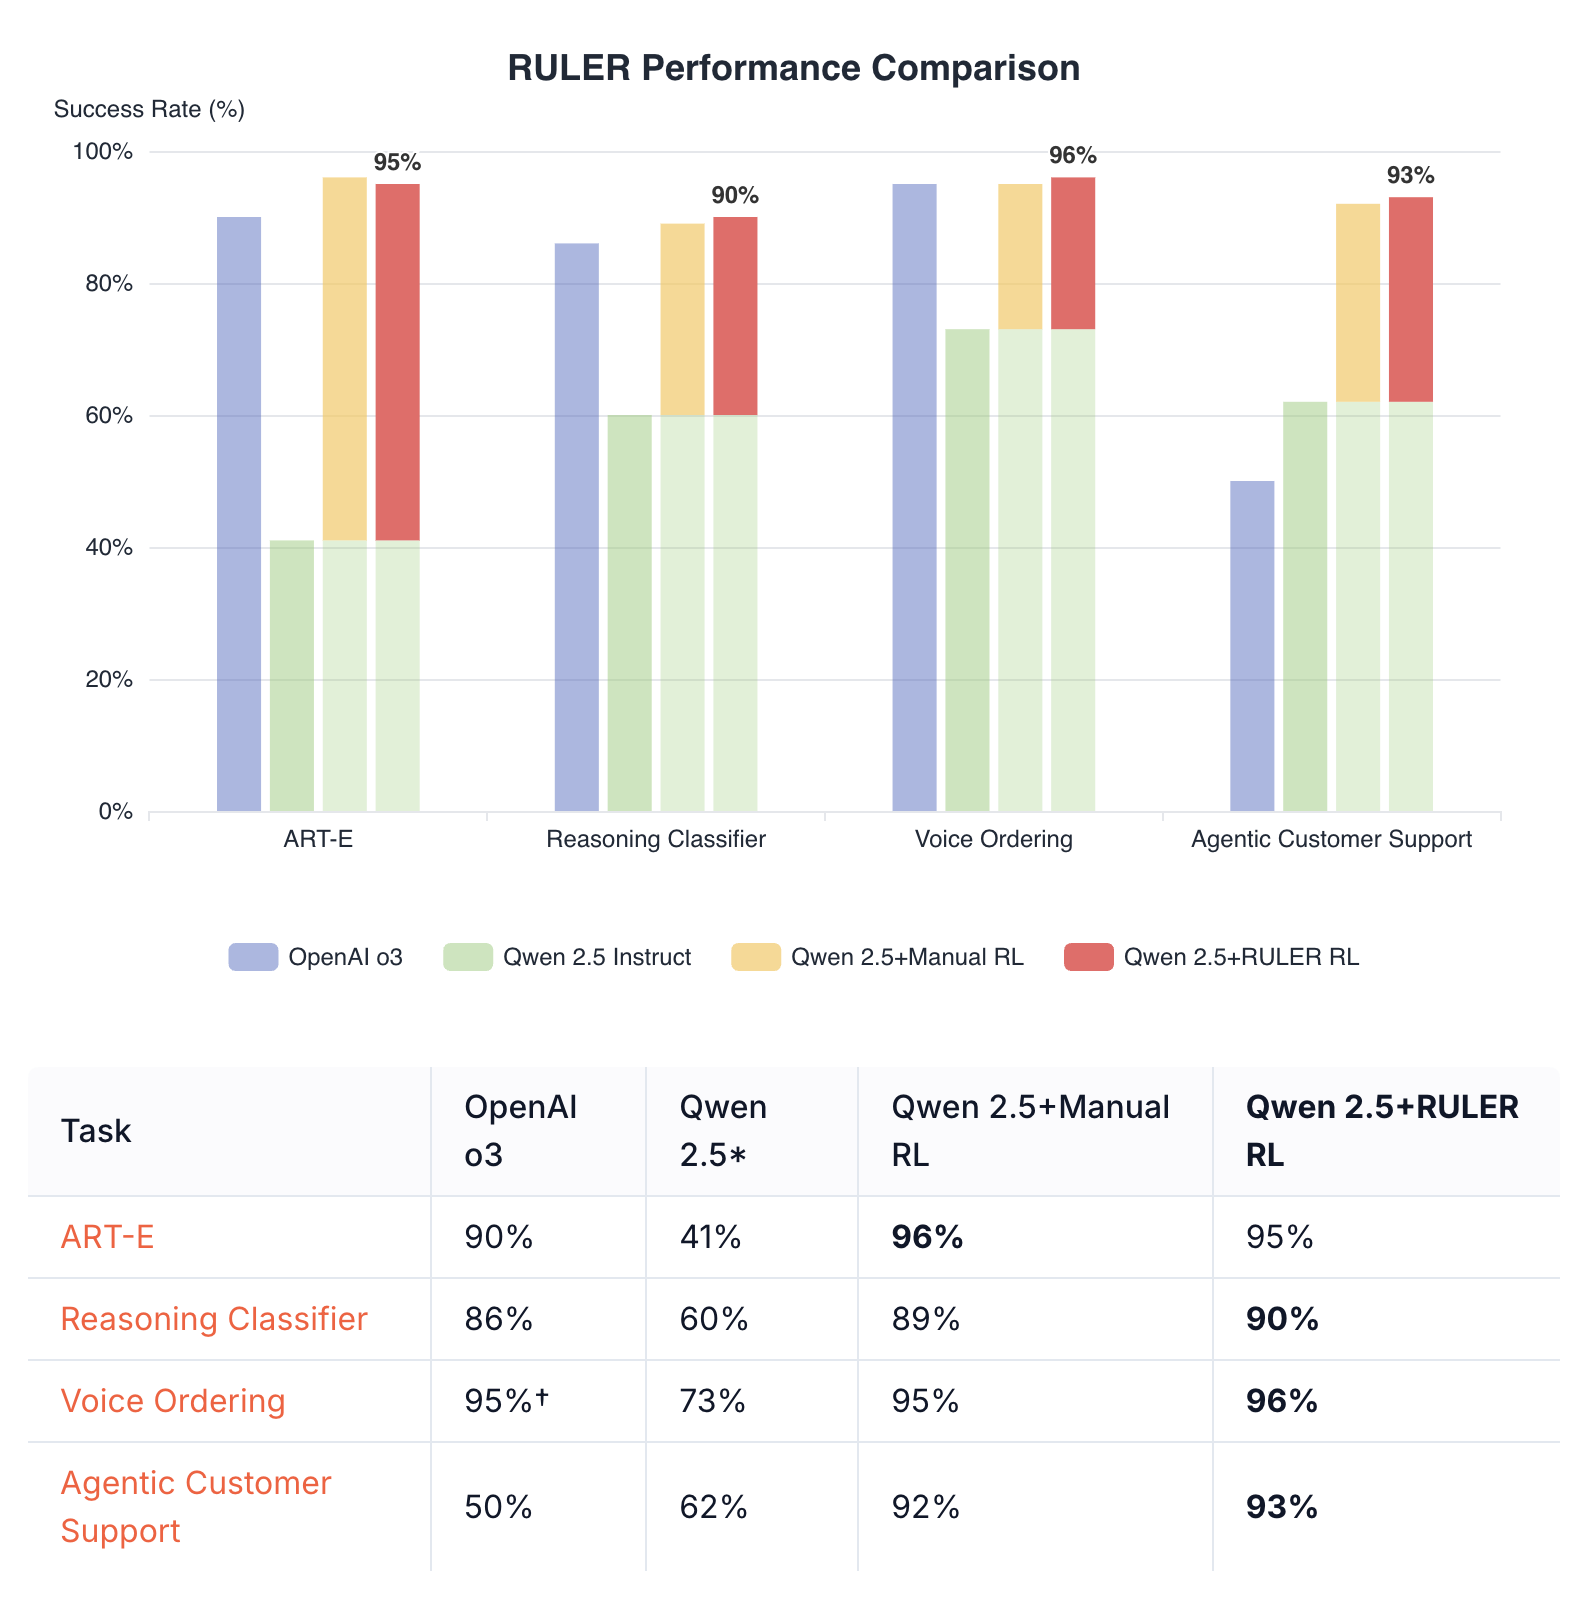
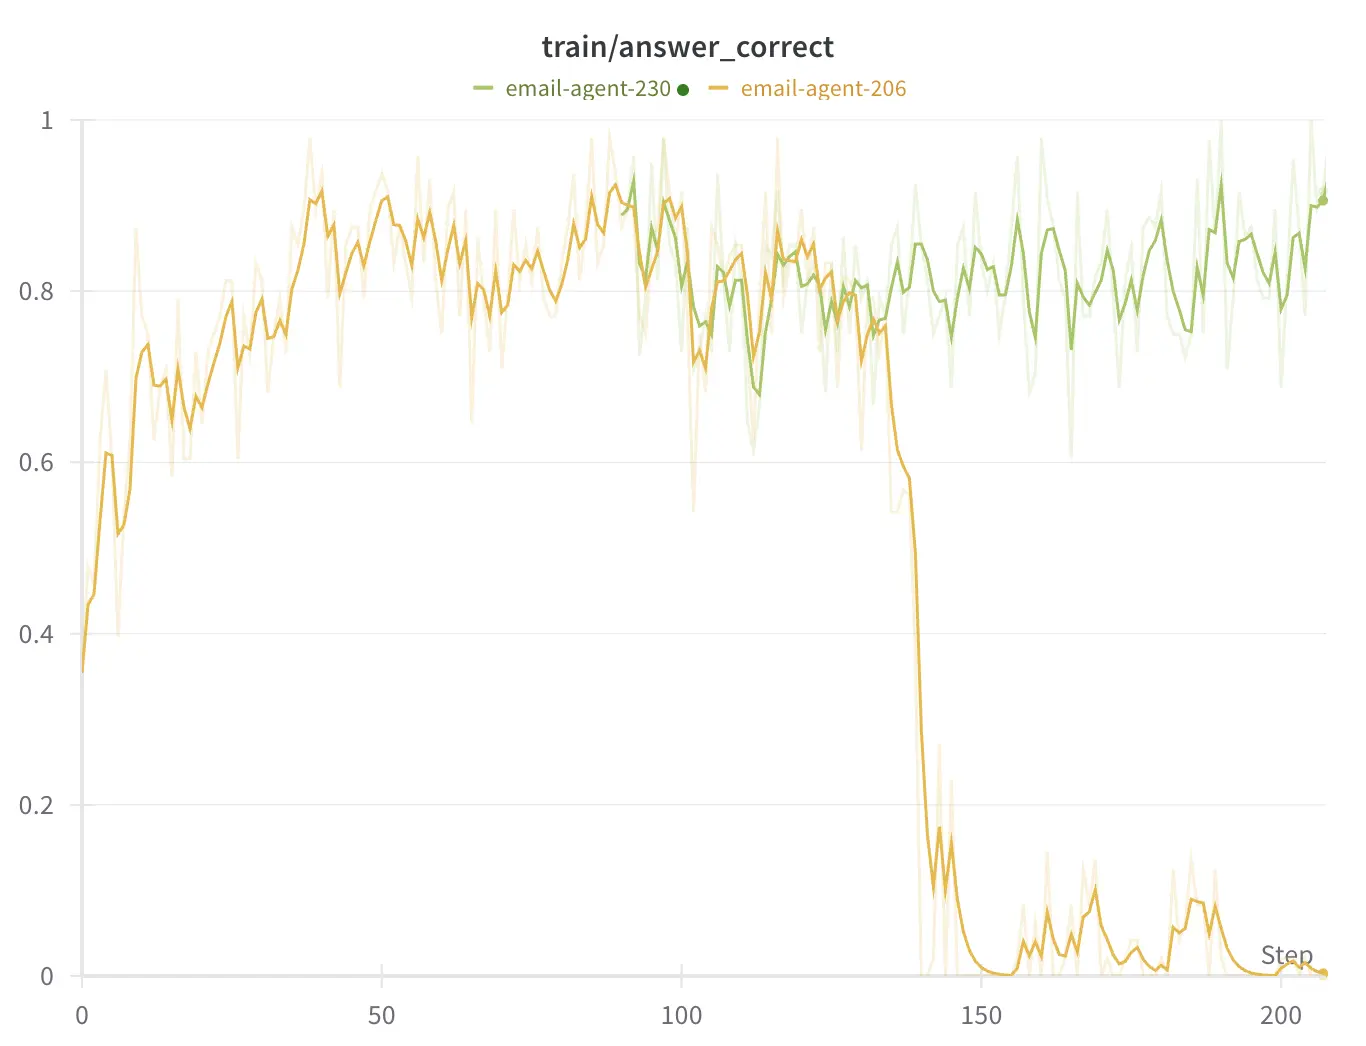
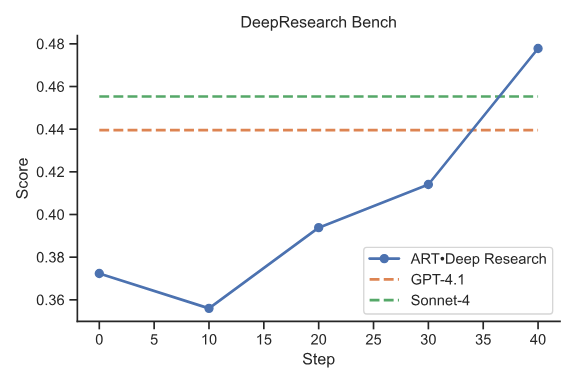
Train a summarizer model to outperform Sonnet 4 and GPT-4.1.
Train a variety of agents in free Colab notebooks.
# Supported Models import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; ## Serverless Models We currently only support the following model for serverless training. We are actively adding support for both larger and smaller models. If there's a particular model you'd like to see serverless support for, please send a request to support@wandb.com. - [OpenPipe Qwen 3 14B Instruct](https://huggingface.co/OpenPipe/Qwen3-14B-Instruct) - Good balance of performance and size. Has support for tool calling and generally trains well. This is our recommended model for users new to RL. - [Qwen 3 30B A3B Instruct](https://huggingface.co/Qwen/Qwen3-30B-A3B) - More capable than 14B while still being efficient. Good choice when you need stronger reasoning capabilities. ## Recommended Local Models If you're developing locally or in your own hardware, here are a couple other models you could try in addition to the recommended serverless list. - [Qwen2.5 7B Instruct](https://huggingface.co/Qwen/Qwen2.5-7B-Instruct) - Less capable than 14B, but smaller and faster - [Qwen2.5 32B Instruct](https://huggingface.co/Qwen/Qwen2.5-32B-Instruct) - More capable than 14B, but larger and slower ## More Models ART has wide support for models supported by [vLLM](https://docs.vllm.ai/en/latest/models/supported_models.html). However, not all models support all features. For instance, if a model's chat template does not include tool call support, you won't be able to use tools with it natively. And if a model's architecture doesn't have support for LoRA layers, it won't be compatible with our LoRA-based backend, but still may work with our full-fine-tuning backend. Here are additional models that we've tested and found to work well with ART: - [Llama 3.1 8B Instruct](https://huggingface.co/meta-llama/Llama-3.1-8B-Instruct) - [Llama 3.2 1B Instruct](https://huggingface.co/meta-llama/Llama-3.2-1B-Instruct) - [Llama 3.2 3B Instruct](https://huggingface.co/meta-llama/Llama-3.2-3B-Instruct) - [Llama 3.3 70B Instruct](https://huggingface.co/meta-llama/Llama-3.3-70B-Instruct) - [Qwen2.5 72B Instruct](https://huggingface.co/Qwen/Qwen2.5-72B-Instruct) - Additionally, the [Qwen 3](https://huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f653967f) family of models is well supported for single-turn workflows. For multi-turn workflows the Qwen 3 chat template removes the `` tokens from previous turns, which makes training more complicated. It is still possible to use for multi-turn workflows by splitting each turn into a separate message history with our `additional_histories` trajectory parameter (see [Additional Histories](/features/additional-histories)). If you're curious about a model that is not listed above, ask in the Discord [#support](https://discord.com/channels/1359674493949448375/1359674622965973185) channel. # Glossary import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; ## Additional Histories A feature that allows a trajectory to contain multiple separate conversation histories. Used for training agents with non-linear conversation flows, preserving special tokens across turns, or handling sub-agent interactions. See [Additional Histories](/features/additional-histories) for details. ## Agent A program that uses an LLM to perform a task. ## Batch Size The number of training scenarios that are run in a single training step. ## Reward Function The function used to assess agent performance and score a trajectory. ## Rollout A single attempt by the agent to complete a training or validation scenario. ## Training Environment The programmatic environment that the agent interacts with. This includes all the tools available to the agent, the data it can query, and any other external aspects of the system the agent is operating in. ## Training Loop The training loop is the process of training the agent. ## Training Scenarios The scenarios that the agent will run through during training. Adding new training scenarios that represent edge cases on which the agent is currently underperforming will help it correct is behavior. ## Training Step A single step in the training loop. During a training step, the agent completes a set of training scenarios and has its performance assessed and weights updated to improve its performance. ## Trajectory A set of system, user, and assistant messages that are produced by the agent in a single rollout. ## Trajectory Group A set of trajectories that the agent produced while completing a single scenario. Differences in trajectory rewards are used to train the agent. ## Trajectory Group Size The number of trajectories in a trajectory group. ## Validation Scenarios Validation scenarios are the scenarios that the agent is evaluated on. These scenarios are used to assess the agent's performance and determine whether it has improved. # GSPO (Group Sequence Policy Optimization) import { Accordion, Card, Frame, Note, Info, Warning, Callout } from "../../../components/mintlify"; GSPO is an experimental feature. The API and behavior may change in future releases. ## Overview GSPO was introduced by the Qwen team to train state-of-the-art models including [Qwen3-235B-A22B-Instruct-2507](https://huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507). It can improve training stability and efficiency for Mixture-of-Experts (MoE) models, and may have limited or no impact for dense models. ## Key Benefits - **Stable Training**: Maintains stable training processes and resolves stability challenges in large MoE models - **Efficient Scaling**: Achieves higher training efficiency and continues improving with increased computational resources - **Infrastructure-Friendly**: More tolerant of precision discrepancies, eliminating the need for complex strategies like "Routing Replay" ## How It Works GSPO's core innovation is its **sequence-level optimization objective**. Instead of focusing on individual token likelihoods, GSPO defines importance ratios based on the **sequence likelihood** with length normalization to reduce variance. The algorithm optimizes: ``` J_GSPO(θ) = E[1/G ∑ᵢ min(sᵢ(θ) Âᵢ, clip(sᵢ(θ), 1-ε, 1+ε) Âᵢ)] ``` Where the importance ratio `sᵢ(θ)` is defined as: ``` sᵢ(θ) = (π_θ(yᵢ|x) / π_θ_old(yᵢ|x))^(1/|yᵢ|) ``` This sequence-level approach makes GSPO more robust to noise and eliminates the need for complex MoE-specific strategies. ## Configuration GSPO can be configured using the `importance_sampling_level` parameter when training with ART: ```python result = await backend.train( model, trajectory_groups, importance_sampling_level="sequence", ) await model.log(trajectory_groups, metrics=result.metrics, step=result.step, split="train") ``` ## Technical Details For a deeper understanding of GSPO's technical foundations and comparative analysis with other RL algorithms, see the [original research paper](https://qwenlm.github.io/blog/gspo/). ## Limitations - As an experimental feature, GSPO may have limited compatibility with some model architectures - Performance characteristics may vary depending on model size and dataset - API is subject to change in future releases